A source connector reads records from an external system and publishes them to Kafka. It is the ingestion side of Kafka Connect, contrasting with a sink connector, which exports Kafka records to another system. Typical sources include databases, filesystems, and messaging systems. section 11.1
Figure 11.1 Kafka Connect integrates third-party systems with Kafka.
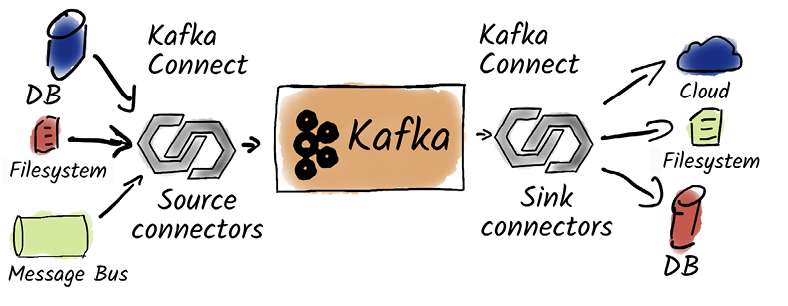
Use the integration diagram to trace data from a third-party system through a source connector into Kafka. section 11.1
A connector class selects the implementation, such as FileStreamSourceConnector, JdbcSourceConnector, or Debezium’s PostgresConnector. Configuration can split work across tasks with tasks.max, although the connector or source structure may limit the effective parallelism. Source data is modeled as partitioned streams so Kafka can scale processing while preserving each stream’s required ordering and tracking progress. section 11.6.1 section 11.1
Database ingestion
A JDBC source connector can read from a database and publish records to Kafka. Database tables can be treated as independent streams, with sequential identifier columns helping track which rows Kafka Connect has already seen. For database changes, a connector such as Debezium can implement change data capture. section 11.1 section 11.10


