A retrieved document is a relevant document or context chunk selected from a knowledge source and supplied to a language model with the user’s query. Retrieval gives a stateless, pretrained model the information it needs to reason about new data. section 4.1
A retrieved document fits into the RAG workflow:
- Retrieve the top k documents or chunks using a similarity metric such as Euclidean distance. section 4.1
- Attach the selected context to a composite prompt containing the user’s question. section 4.1
- Let the language model generate an answer grounded in the supplied context. section 4.1
Pet question
For “Who is the nasty cat?”, retrieval selects chunks stating that Fox is not well-mannered, Kit is cute, and Brian is a good kitten; the model answers, “Fox is the nasty cat.” section 4.1
Figure 4.1 A RAG-based flow includes three essential steps: document ingestion, document retrieval, and answer generation.
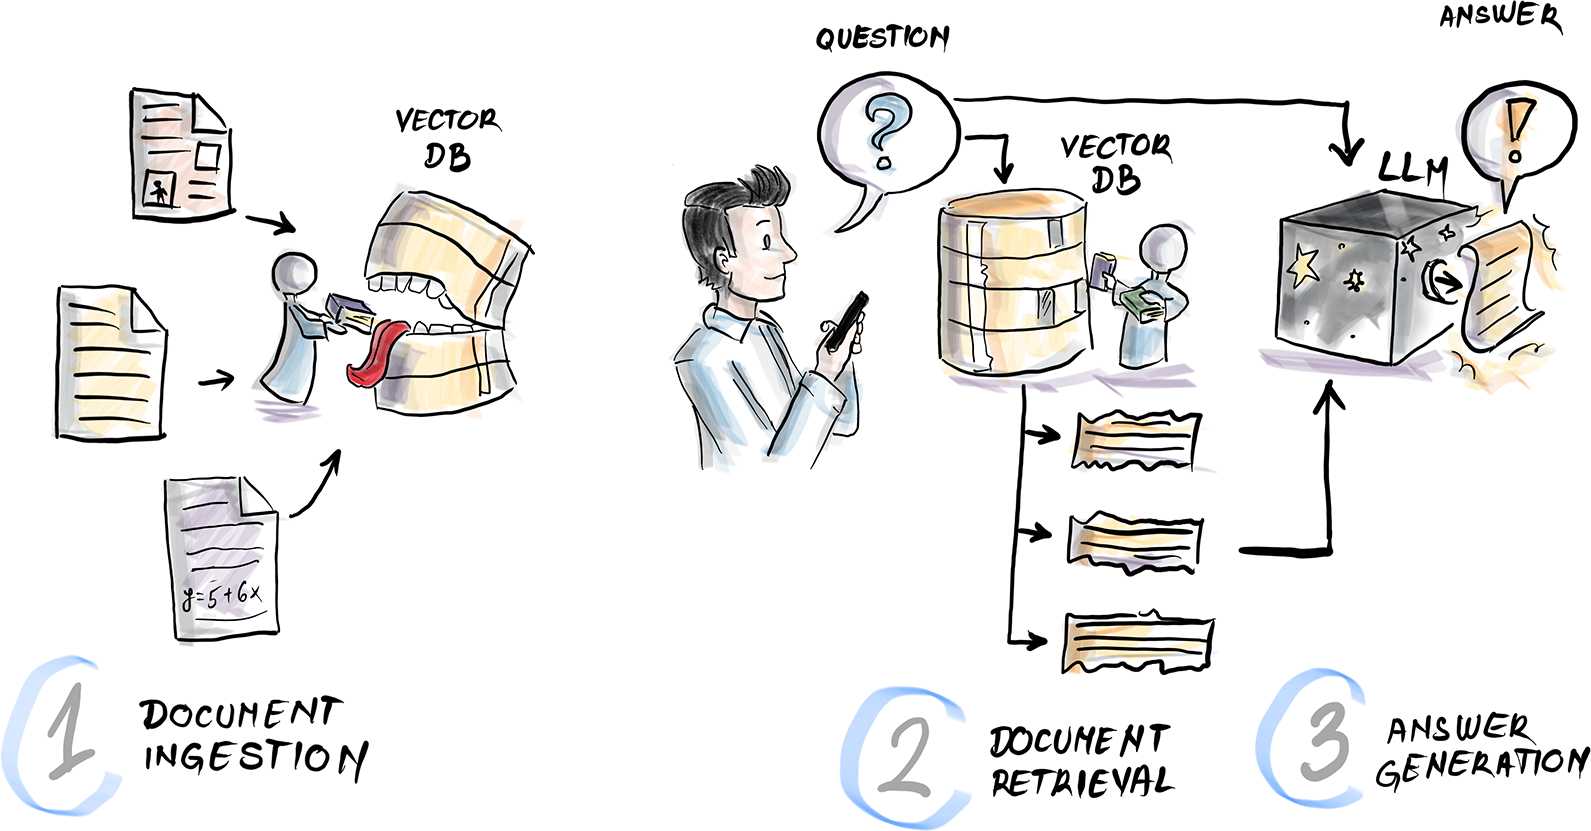
Trace retrieved documents through ingestion, retrieval, and answer generation in the RAG flow. section 4.1

