Spark Migrator moves data from Cassandra-compatible databases into ScyllaDB by using Apache Spark to divide migration work across multiple workers. Its parallel design scales beyond the table-level parallelism of SSTableLoader. section 12.2.2 section 12.2.3
Use Spark Migrator when migration speed and elastic parallelism justify the operational setup:
- Run more machines to process more data concurrently, subject to source and destination bandwidth and migrator compute. section 12.2.3
- Filter rows with a WHERE clause and use checkpointing to pause and resume progress. section 12.2.3
- Migrate from Cassandra or ScyllaDB; support also exists for Amazon DynamoDB and Apache Parquet, but not PostgreSQL. section 12.2.3
- Provision machines, install Spark and the migrator, and consider Dataproc or EMR for cloud setup. section 12.2.3
Migration validation
After migrating, compare source and destination data with the built-in validation function, then dual-read application requests and investigate mismatches. Repeated reads can reduce noise from rows updated between comparisons. section 12.2.5 section 12.3
Figure 12.6 The Spark Migrator offers greater scalability than Scylla’s SSTableLoader.
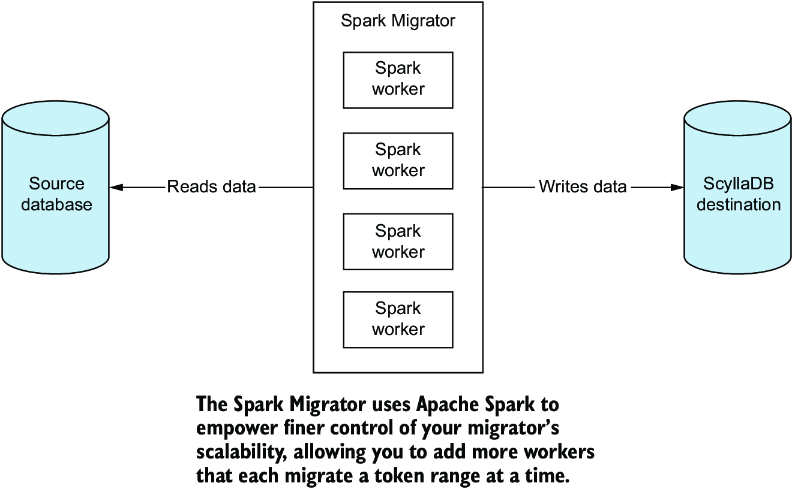
Use the scalability figure to compare Spark Migrator’s worker-based parallelism with SSTableLoader’s narrower table-level parallelism. section 12.2.3
