Sparse dispatch routes each token to a small top-k subset of experts, batches tokens selected by the same expert, and restores results to their original positions. Router logits receive a balancing bias; top-k scores become normalized gates. section 4.5
An implementation follows four tensor operations:
- Compute router logits and add the dynamic expert-load bias. section 4.5
- Select top-k expert indices and calculate softmax gate weights. section 4.5
- For each expert, mask selected token rows, gather them with nonzero indices, and process the resulting batch. section 4.5
- Multiply expert outputs by their gates and use index_add_ to accumulate them at the original token positions. section 4.5
Routed-path accumulation
With topk_idx == i, the boolean mask identifies every token assigned to expert i. row_idx selects those tokens, which_k selects their gate values, and index_add_ writes weighted outputs into routed_out. Shared-expert output and the routed result then join the final MoE output. section 4.5
Figure 4.27 The complete forward pass of the DeepSeekMoE module, showing the three parallel data paths: the dense shared expert path, the sparse routed expert path with dynamic load balancing, and the residual connection.
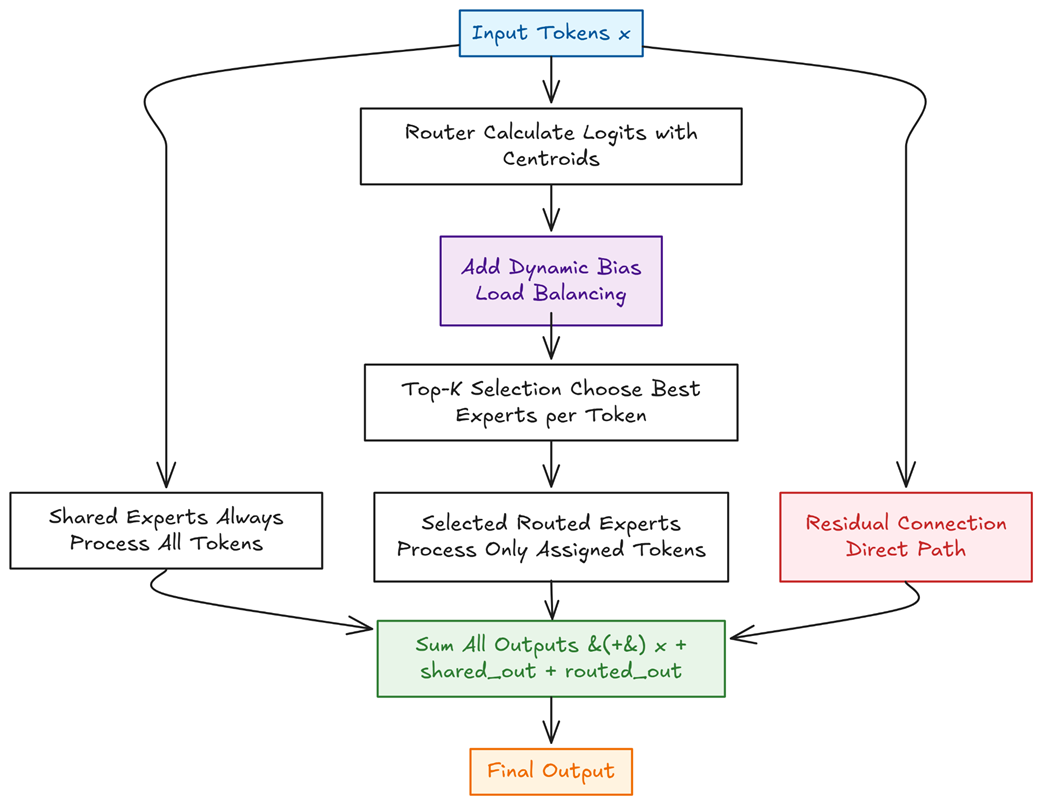
Use the forward-pass diagram to trace the shared path, sparse routed path, dynamic load balancing, and residual combination together. section 4.5
