SPMD (Single Program, Multiple Data) applies the same program to multiple independent portions of data. Each instance runs the same code on a different slice. SPMD describes the programming pattern, not the hardware execution model. section 2.1.2
Triton uses blocked, or tiled, SPMD: each program instance handles a block of elements rather than a single element. A program ID determines which chunk it processes, so identical code covers consecutive chunks. section 2.1.2 section 2.2.4
Figure 2.2 CUDA distributes work across many individual threads that each operate on a single element. Triton distributes work across blocks of elements, with each program instance processing one tile as a unit. This shift changes the granularity of parallelism and simplifies the programming model.
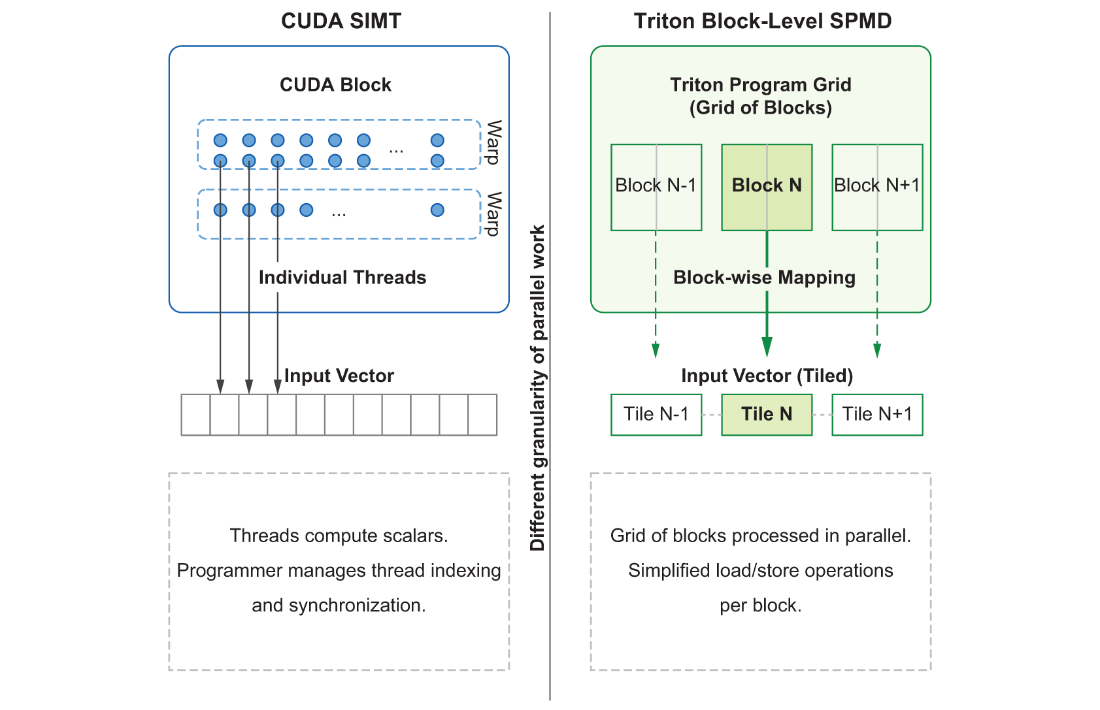
Compare CUDA’s one-thread-per-element mapping with Triton’s one-program-per-tile mapping to see how the unit of work changes. section 2.1.2
Vector addition
For Z = X + Y, each instance adds corresponding chunks of X and Y and writes its results to Z. A grid of program instances covers the full vector. section 2.2


