String similarity measures how closely textual sequences match. In entity resolution, it provides an initial signal for linking mentions that may refer to the same real-world entity. section 6.1.4
Use similarity as one signal in a graph-based resolution pipeline:
- Compare textual representations and create META_SIMILAR links for identical or very similar mentions. section 6.1.4
- Combine similarity with graph context, such as shared WORKS_FOR relations or research topics. section 6.1.4
- Set thresholds with domain rules: combine surname and first-name information rather than relying on surnames alone. section 6.1.4
Resolving person-name mentions
“Eleanor Smith” and “E. Smith” become stronger candidates when both mentions work for the same university; generic words such as “Foundation” should not create similarity links by themselves. section 6.1.4
Figure 6.3 Graph-based entity resolution example
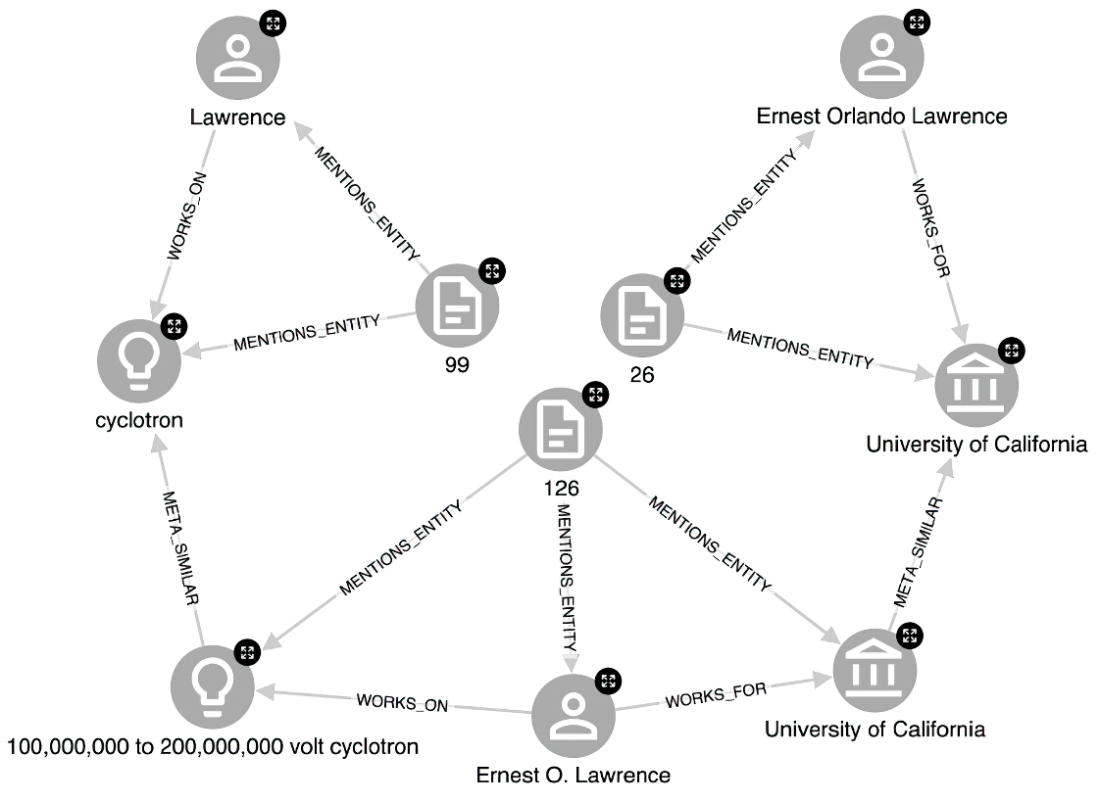
Use the graph-based example to inspect how textual similarity and neighboring relations support entity resolution. section 6.1.4

