A subtopology is one part of a Kafka Streams processing topology, separated from another part by an intermediate topic. This split lets processing continue after data is written to and read back from a repartition topic. section 12.6
Kafka Streams needs this boundary when processing must be coordinated by key, such as during a join or aggregation. The first subtopology writes to an internal topic ending in -repartition; the second reads from it and continues processing. The design improves correctness but increases network traffic and storage requirements. section 12.6 section 12.7
Changing a key before counting
A topology that calls selectKey() and then count() changes the record key before aggregation. Kafka Streams therefore repartitions the data, creating one subtopology for selectKey() and another for reading the repartitioned data and performing the count. section 12.6
Figure 12.14 If we first execute a selectKey() and then an aggregation such as count(), the topology needs to be split up into multiple subtopologies.
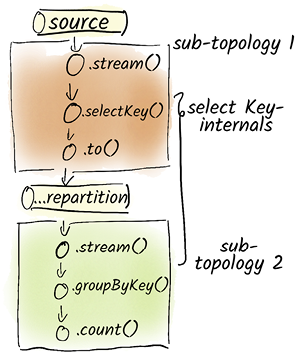
Use the topology diagram to trace how selectKey() followed by an aggregation divides processing into multiple subtopologies. section 12.6

