Synchronous model update keeps data-parallel workers aligned by pausing each training iteration during gradient synchronization. After every worker receives the aggregated gradients, all devices update shared model parameters and begin the next iteration together. section 4.2.1
Use the synchronization barrier deliberately because it trades consistency for throughput:
- Preserves the same model state across workers at every training iteration. section 4.2.1
- Blocks the whole group while gradients synchronize, leaving faster workers idle when machines or networks lag. section 4.2.1
- Adds relatively little implementation change to single-device training beyond gradient aggregation synchronization. section 4.2.1
Figure 4.1 A synchronous data parallelism concept graph. (a) Deep learning training on a single GPU. (b) Synchronous data parallel training with three GPUs.
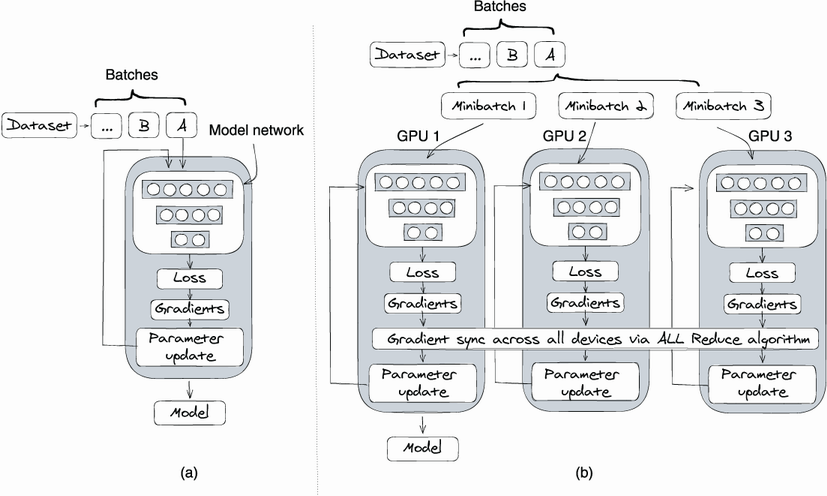
Compare single-GPU training with three-GPU synchronous data-parallel training and locate the synchronization point in the workflow. section 4.2.1
