Text-to-video generation synthesizes short video scenes from textual descriptions. Prompts can specify artistic styles, imaginary imagery, or real-world situations, while the model aims to preserve visual quality and follow the instructions. section 1.3.7
The method associates words and phrases with visual concepts, then generates video matching the prompt. Sora uses a diffusion approach: it starts with noisy video frames and progressively removes noise to produce detail, rather than directly predicting each frame. section 5.4
Related generation approaches include:
- Image-to-video synthesis generates motion from a source image. section 5.4
- Video-to-video synthesis transforms an existing video while preserving its underlying structure. section 5.4
- GAN-based video generation uses a generative adversarial network to create video. section 5.4
Prompted scene generation
A user can describe a realistic scene, an imagined setting, or a particular artistic style and receive a short generated clip. Sora can produce clips up to a minute long with coherent characters and movements; other options include Runway Gen-2, Pika, Hotshot, and Stable Video Diffusion. section 1.3.7
Figure 5.15 Wochit AI video generation
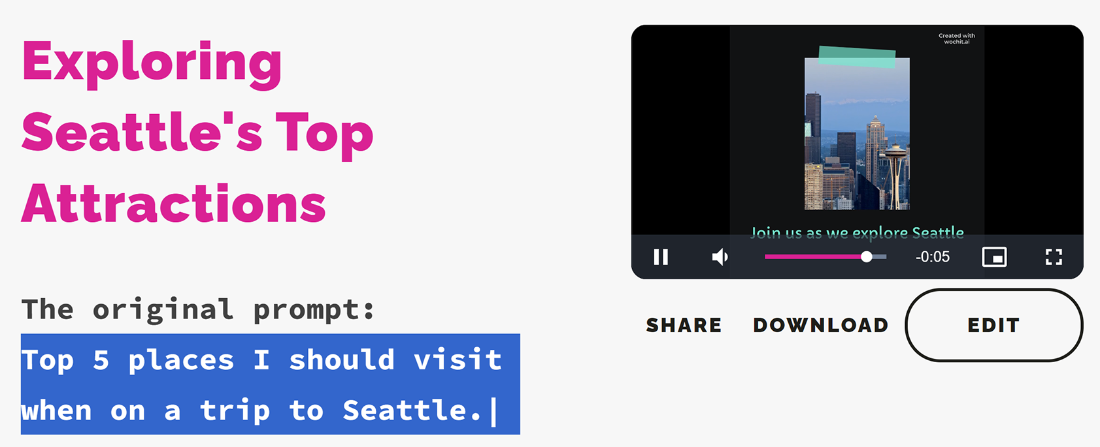
Use the Wochit AI video-generation figure as a visual companion to prompt-driven video creation. section 5.4

