Threads in the same CUDA block can pass data through shared memory: one thread writes a value, and another reads it. Think of shared memory as a block’s whiteboard—fast to access, but private to that block and gone when the block finishes. section 11.2
Passing a value between threads
Thread 0 writes a value to shared memory; Thread 5 reads it. Place __syncthreads() between the write and the read so the reader does not proceed before the write is complete. section 11.2 section 11.14
Keep these boundaries in mind:
- Shared memory is visible only to threads in its owning block; it does not pass data between blocks. section 11.14
- Use a block-wide barrier after a shared-memory write another thread will read. Do not place the barrier in a divergent branch. section 11.14
- For dependencies between blocks, use separate kernel launches; __syncthreads() cannot synchronize across blocks. section 11.14
Figure 11.2 Shared memory physically lives inside each SM. Each SM owns one SRAM that is divided into a separate slot per resident block, so blocks on the same SM stay isolated and blocks on different SMs share nothing. The pool is finite (SM 0 has slack, SM 1 is fully packed, and SM 2’s pool is exhausted, leaving Block 2 with no slot, so it waits until a resident block finishes and frees one), while global memory (DRAM) below is slow, large, and shared by every block.
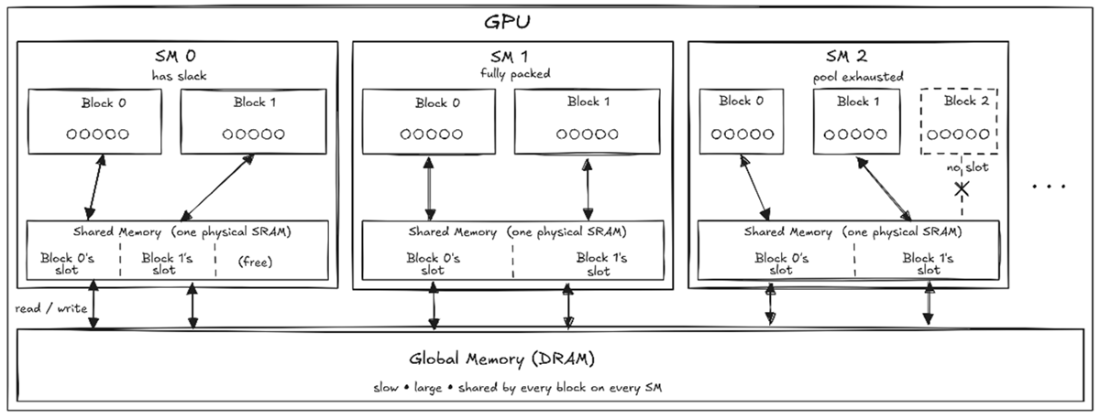
The figure shows how shared memory is allocated per block within an SM, clarifying why blocks cannot use it to communicate with one another. section 11.2

