Measure decode throughput at multiple configured thread counts to find a suitable setting; do not assume the physical-core count is optimal. section 10.5.2
SMT can change the result
On an 11-core c3-standard-22 VM, throughput rose from 16.62 tok/s at 11 threads to 21.02 tok/s at 22, a 26% gain. It dipped 4.9% at 12 threads. Absolute rates vary across VMs, so treat these figures as an example, not a portable benchmark. section 10.5.2
Figure 10.12 Decode throughput on c3-standard-22 (Sapphire Rapids, 11 physical cores × 2 SMT) versus llama.cpp -t thread count, AVX-512+VNNI build, Q4_K_M Llama-2-7B, n=64 token generation, mean over 5 repetitions. Throughput climbs through the full vCPU count rather than peaking at the physical-core count: 16.62 tok/s at t=11 lifts to 21.02 tok/s at t=22, a 26% gain that the kernel extracts by recruiting SMT siblings. A local minimum at t=12 (15.81 tok/s, 4.9% below t=11) marks the first SMT-sibling activation under L1/L2 contention; throughput recovers past t=14 once enough cores share that pattern. The dashed line at t=11 marks the physical core count; the dashed line at t=22 marks the full vCPU count.
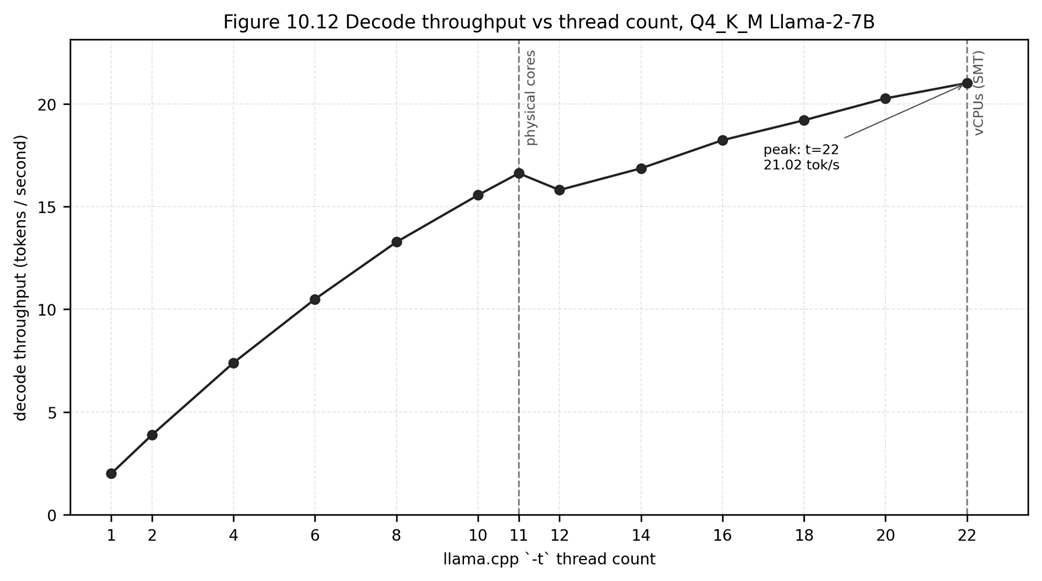
Compare decode throughput across the thread counts, including the dip at 12 and the rise through the full vCPU count. section 10.5.2
