liveBook · Manning

Token embedding

As explained in Rearchitecting LLMs

A token embedding is a vector representation encoding the identity or learned meaning of a token independently of its surrounding sequence context.

A token embedding is the vector assigned to a token ID. In DistilGPT2, the wte layer maps tokenizer IDs to 768-dimensional vectors; positional embeddings are added afterward to form input embeddings. section 3.1.1

Figure 3.1 Embedding creation process in the input block. The wte layer converts each text token into a Token Embedding based on its meaning. The wpe layer generates a Positional Embedding based on the token's position in the sequence. The combination of both produces a vector that contains both semantic and positional information.
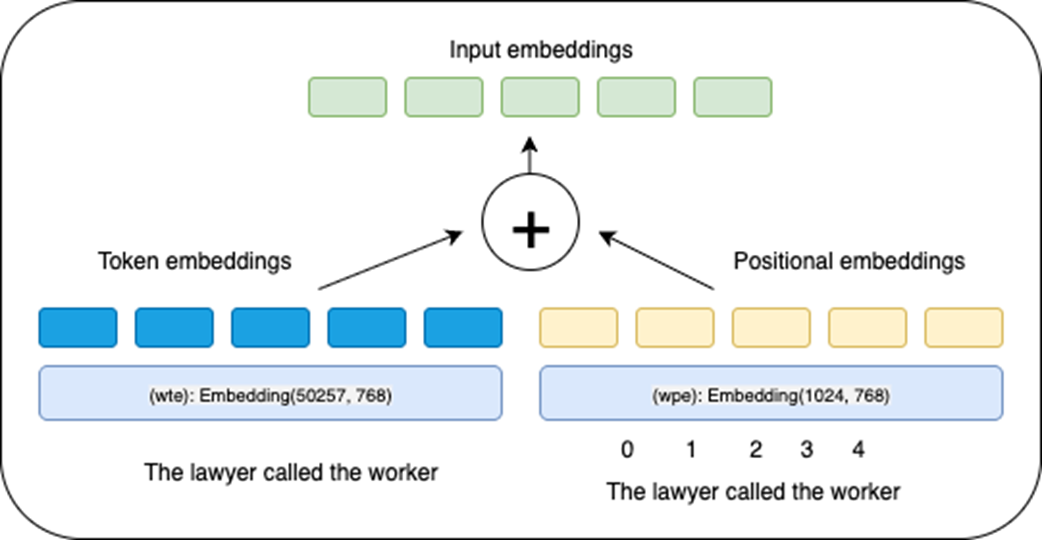
Shows token and positional embeddings combining to form an input embedding. section 3.1.1

How Rearchitecting LLMs covers it

How deep it goes
Defines the lookup and vector dimensions, without detailing how embedding values are learned.
Examples
Uses DistilGPT2’s 50,257-entry vocabulary and 768-dimensional token vectors.
What it assumes
Assumes tokenization has converted input text into IDs before the model receives them.
What you can do after
Understand how token IDs become vectors before positional information is added.
How it connects
Connects token IDs from a tokenizer to positional embeddings and input embeddings.

Related concepts

This explainer was generated by Manning's knowledge graph from the text of Rearchitecting LLMs. The section links point to the parts of the book it draws on.