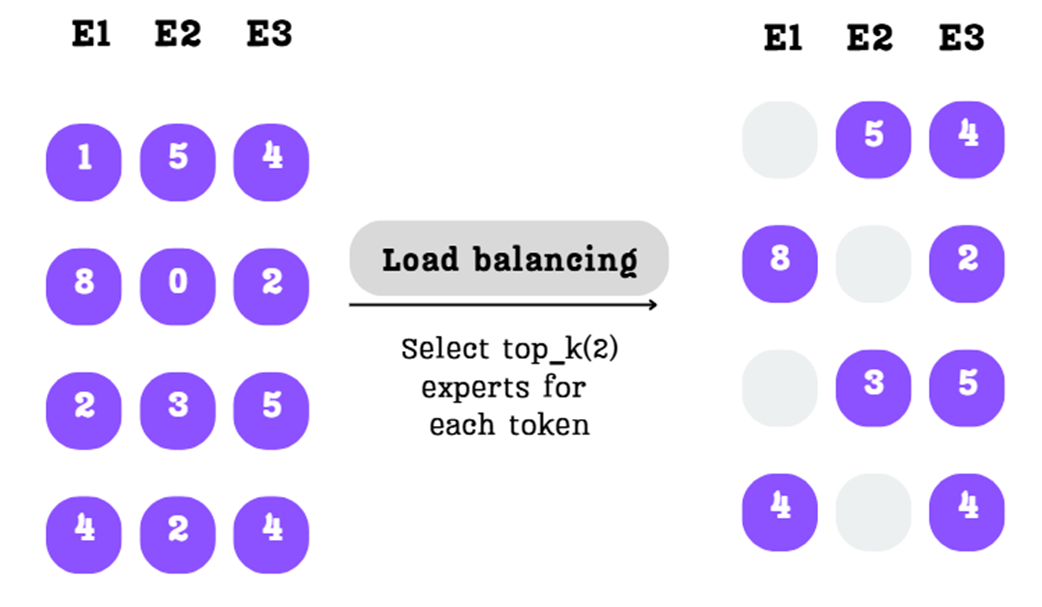
Top-k selection makes Mixture-of-Experts computation sparse: each token activates only its k highest-scoring experts, leaving the remaining experts dormant. With three experts and k=2, every token uses two expert paths instead of all three. section 4.2.2
Implement top-k routing as a score-filtering pipeline:
- Generate one raw score for every token–expert pair with the learned routing mechanism. section 4.2.3
- Select the k largest scores in each token row and discard the rest. section 4.2.4
- Replace discarded scores with negative infinity so softmax assigns them zero weight. section 4.2.4
- Apply softmax to the masked row, producing nonzero expert weights that sum to one. section 4.2.4
Three experts, k=2
For the token "The," suppose the router scores E1, E2, and E3 as 1, 5, and 4. Keep E2 and E3, mask E1, and normalize the survivors; the resulting weights can be 60% for E2 and 40% for E3. section 4.2.4
Figure 4.8 The top-k selection process. For each row, only the two highest scores are kept, and the rest are masked out.
Visualize row-wise top-k selection before masking the discarded experts. section 4.2.4


