Top-k gating routes each token to a small, specialized subset of experts. A router scores every expert, adds a dynamic balancing bias, selects the highest-scoring k experts, and normalizes their scores with softmax. section 4.5
An implementation proceeds through four tensor operations:
- Dispatch tokens by expert using a boolean mask and nonzero indices, process each batch through its expert, and add weighted outputs back with index_add_. section 4.5
Figure 4.27 The complete forward pass of the DeepSeekMoE module, showing the three parallel data paths: the dense shared expert path, the sparse routed expert path with dynamic load balancing, and the residual connection.
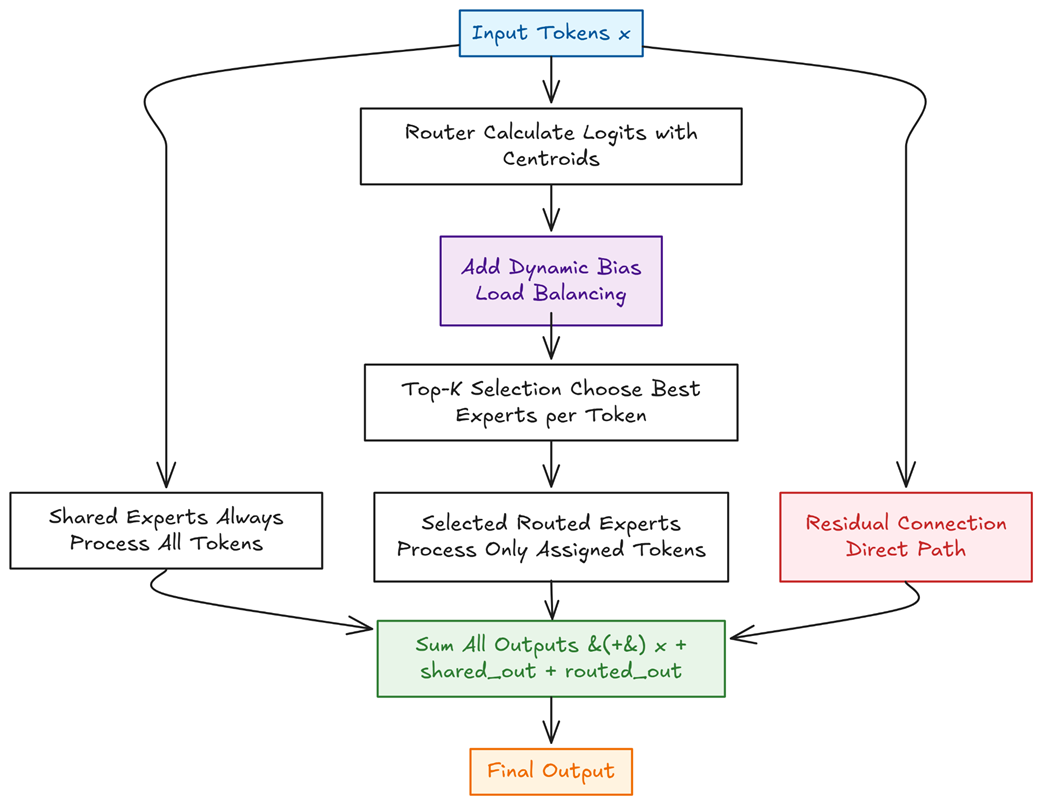
Trace top-k gating within the complete DeepSeekMoE flow, alongside shared experts, routed experts, and the residual connection. section 4.5

