A transient failure comes and goes: after one occurrence, the probability of another is not elevated, and the failure resolves automatically without intervention. section 3.3.3
Think of the failure as temporary disruption rather than a lasting change in system behavior. Its defining guarantee concerns recurrence probability and automatic repair, not the absence of operational impact. section 3.3.3
Distinguish transient failure from nearby temporal classifications:
- Intermittent failures also repair automatically, but a second occurrence is more likely after the first and may take longer to resolve. section 3.3.3
- Permanent failures generally require manual repair rather than resolving automatically. section 3.3.3
A router restart
A failed connection caused by a router restart can be transient: once the router restarts, the connection can be made again. section 3.3.3
Short absences
In a distributed workplace analogy, an employee taking a short break represents a transient failure; a vacation represents an intermittent failure, while leaving represents a permanent failure. section 1.6
Transient failures matter because recovery can preserve a useful execution outcome. A failed and recovered process may be considered equivalent to a failure-free execution under an application-defined equivalence function, even when some events are duplicated. section 11.3
Figure 3.12 Transient failure
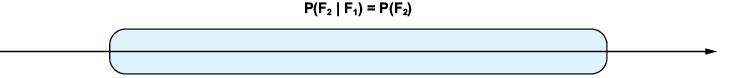
Visualizes transient failure as a temporal classification alongside intermittent and permanent failures. section 3.3.3

