A trust region limits how far an optimization update may move while reliable progress is expected. In PPO, it caps policy changes through the policy ratio ρ, keeping updates within 1 ± ε. section 6.2.6
PPO’s clipped objective creates three operational zones:
- Inside the region, PPO behaves like an ordinary policy-gradient method and applies the full gradient step. section 6.2.6
- At the boundaries, the clip and minimum/maximum operations limit the objective’s pressure to change the policy ratio. section 6.2.6
- Outside the region, the objective becomes flat, preventing further improvement from pushing the update farther in that direction. section 6.2.6
Positive advantage
When an action has positive advantage, PPO increases its likelihood while the ratio remains below the upper clipping boundary; beyond that boundary, the clipped objective stops adding pressure. section 6.2.6
Figure 6.5 Visualization of the different regions of the PPO objective for a hypothetical advantage. The “trust region” would be described as the region where the policy ratio \(\rho\) is within \(1\pm\varepsilon\).
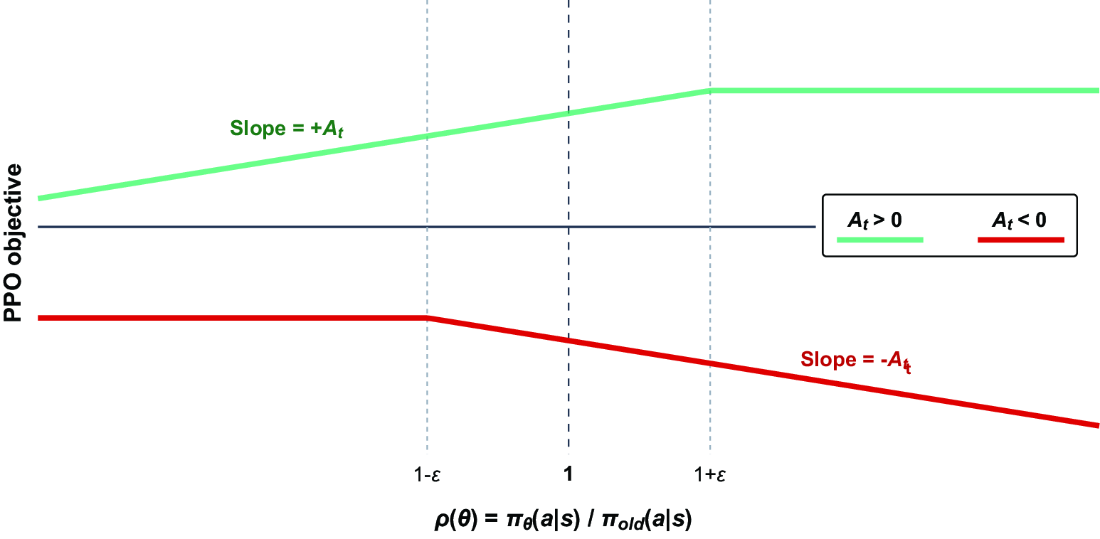
Visualizes the PPO objective’s clipped and unclipped regions, with the trust region defined by ρ within 1 ± ε. section 6.2.6
