The Universal Transformer repeatedly applies shared self-attention and feed-forward layers to refine token representations. It brings recurrence into Transformer processing, where self-attention lets tokens interact across a sequence. section 5.1.2
Figure 5.2 The Universal Transformer. Used with permission granted by the lead author (Mostafa Dehghani).
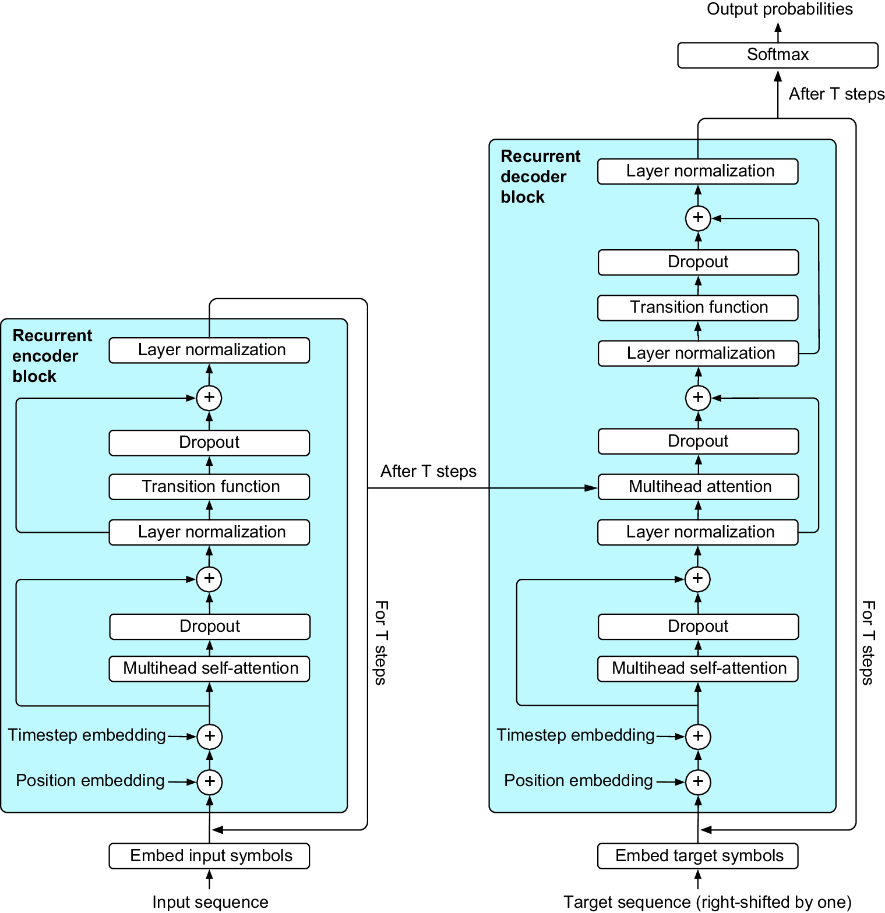
A schematic of the Universal Transformer’s shared-layer design. section 5.1.2
