An upsert conditionally inserts new records and updates existing records according to matching logic. In Iceberg ingestion, it supports transactional pipelines where incoming data reconciles with stored data. section 6.3.1
Upserts create new Iceberg snapshots rather than modifying existing data files. Compute engines such as Spark and Flink execute MERGE operations and translate them into Iceberg-compatible commits, so engine support, delete handling, compaction, performance, cost, and correctness remain architectural considerations. section 6.3.1 section 6.3
Spark MERGE
A staging dataset is matched against the target on an identifier; matching rows are updated, while unmatched rows are inserted. This supports slowly changing dimensions, late-arriving data, and reconciliation workflows. section 6.4.1
Figure 6.10 Merge transactions allow you to compare records to a staging dataset and conditionally insert, update, and delete records.
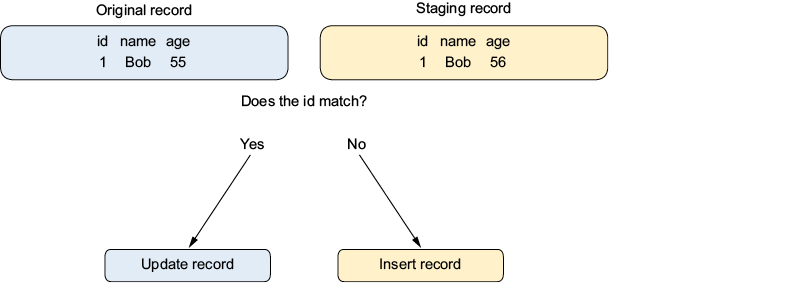
Compare a staging dataset with a target and conditionally insert, update, or delete records. section 6.3.1


