An interaction matrix stores measured or predicted interactions between two entity sets. In drug discovery, it organizes drug–target pairs and their binding-affinity values for machine-learning benchmarks. section 11.1.1
A practical representation uses:
- Drugs and protein targets as the two entity sets. section 11.1.1
- Measured dissociation constants (Kd), converted from nanomolar units to pKd so higher values indicate stronger affinity. section 11.1.1
DAVIS kinase-selectivity matrix
The DAVIS dataset records interactions for 68 unique drugs and 442 protein targets, forming 30,056 drug–target pairs. A curated version removes nine records and contains 433 kinases. section 11.1.1
Figure 11.2 Distribution of pKd Affinity Values in the DAVIS Dataset and KIBA scores in the KIBA Dataset. For the DAVIS dataset, we observe a very large, sharp peak visible at the y-value of 5, with a much smaller, broader distribution of values between 6 and 10.
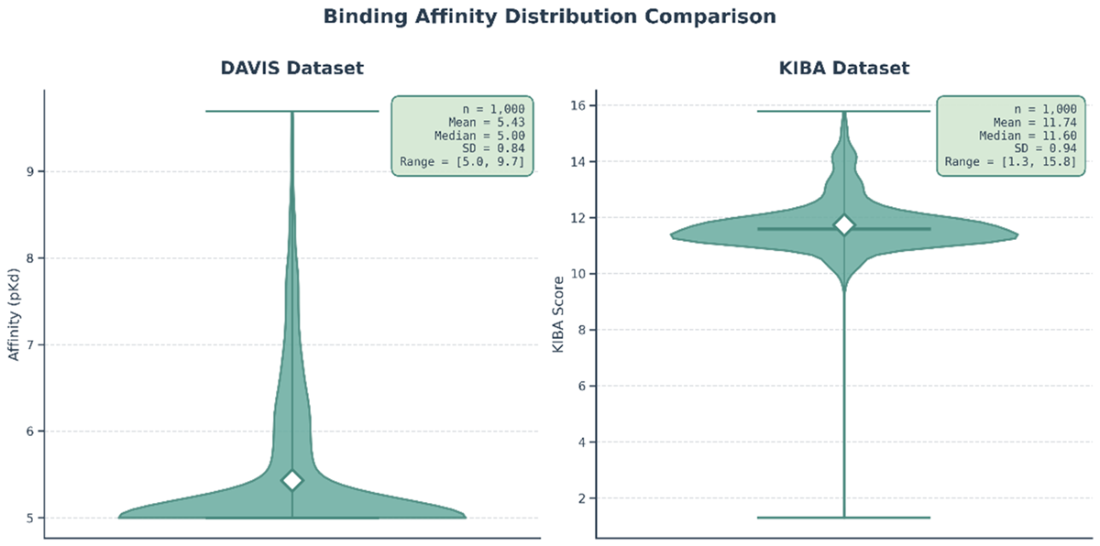
Inspect the distribution of pKd values to see how interaction strengths are distributed across the benchmark. section 11.1.1



