In Transformer attention, a value is a learned representation of information a token can contribute to another token’s representation. A learned projection produces each token’s value, alongside separate query and key projections: queries and keys help determine relevance, while values carry the information shared. section 4.1.3
An attention pattern determines how strongly tokens relate; the model combines their values according to that pattern to form a context-enriched hidden state. In cross-attention, queries come from the decoder’s current state, while keys and values come from the encoder’s representations. section 4.1.3 section 4.1.7
From “rises” to “east”
For “rises,” the query may match the key for “sun” more strongly than the key for “the”; the corresponding value carries information that can contribute to “rises” becoming context-aware. When predicting “east,” the decoder can use cross-attention to retrieve relevant information from the encoder’s input representations. section 4.1.3 section 4.1.7
Figure 4.3 A single token representation is transformed by three learned projections into a query, key, and value, which serve different roles in attention. The query represents what the token looks for in context, the key what makes it potentially relevant to other tokens, and the value the information it can contribute.
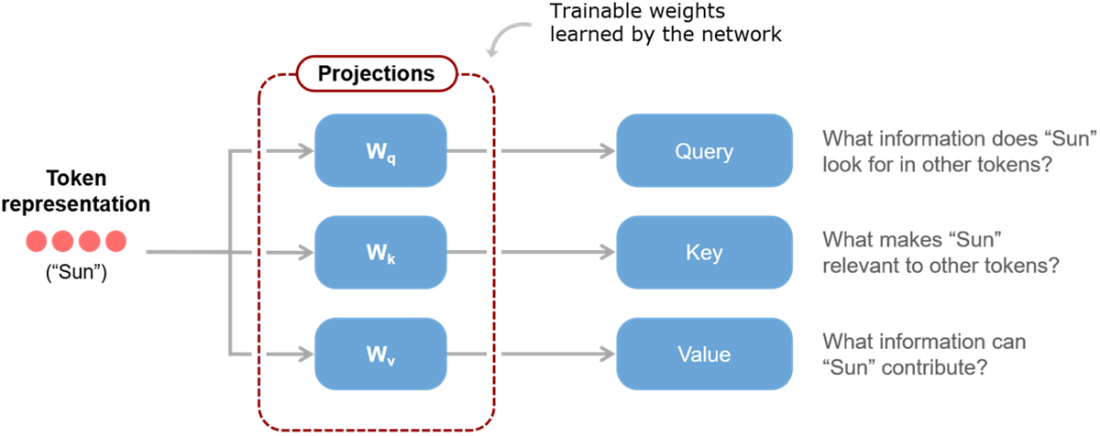
Shows how separate learned projections give query, key, and value distinct roles. section 4.1.3

