To compare a search query with documents, first give them the same set of dimensions. That shared set is a vector space. Each vector supplies a value for every dimension, so values at the same position describe the same feature. For houses, the dimensions might be price, size, and bedrooms; [100000, 1000, 2] describes one house in that space. section 2.3
A query and its documents
Suppose two documents contain 48 distinct words between them. Give each word a dimension. The query “apple juice” becomes a 48-value vector: 1 at the positions for “apple” and “juice,” and 0 elsewhere. Map both documents using that same word order. Their vectors can then be compared with the query vector rather than treated as unrelated lists of numbers. section 3.1.1
Figure 3.1 Query vector. The query for apple juice is mapped to a vector containing one dimension for every known term, with a value of 1 for the terms “apple” and “juice” and a value of 0 for all other terms.
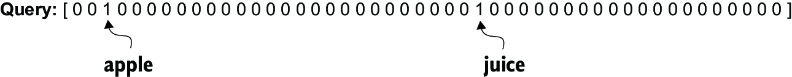
The query-vector diagram shows why even a two-word query needs a position for every term in the shared space. section 3.1.1
Dimensions need not be literal words. An embedding places a query or document at numerical coordinates intended to represent information such as meaning. A dense-vector search index stores document embeddings and compares them with a query embedding at search time. Both must occupy the same vector space: comparing coordinates from different spaces would be like comparing different attributes merely because they appear in the same positions. Similarity measures, including cosine similarity, can then help rank matches. section 2.3 section 13.2.2
Choose what each indexed embedding represents as well as which space it uses. A long document may be split into sentence, paragraph, or overlapping chunks, each with its own embedding, so a relevant passage can be matched without requiring one vector to represent the whole document. section 13.2.2



