Verifiable rewards turn correctness into a deterministic training signal. A verifier checks a generated answer against a reference solution, then assigns a reward such as 1 for correct or 0 for incorrect. section 3.0 section 6.1.2
A verifiable-reward workflow:
- Generate a response for a problem. section 6.1.2
- Run a deterministic verifier against the correct solution and required output format. section 6.13
- Use the resulting reward directly to update the model, without a learned reward model or human annotation. section 6.1.2
Figure 6.6 Overview of RLVR. The LLM generates a response that is evaluated by a deterministic verifier, such as the math verifier from chapter 3, which assigns a correctness label that’s used as a reward signal within an RL objective to update the model.
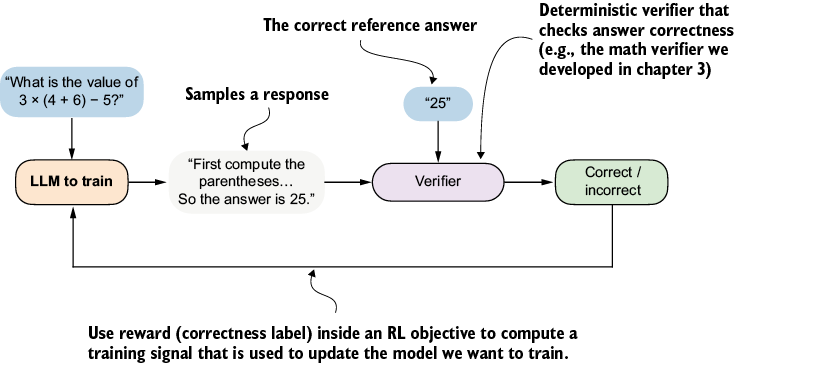
Follow the response-to-verifier-to-reward-to-update flow used by RLVR. section 6.1.2

