A VQGAN encoder maps an image to a sequence of discrete image tokens. It first creates a continuous latent representation, then replaces each latent feature vector with the nearest entry in a learned codebook. section 1.2.2 section 11.5.2
Trace the image through the encoder:
- Encode a 384 × 384 image through four strided convolutional layers, reducing its spatial resolution by 16 to a 24 × 24 latent grid. section 11.5.2
- Apply quant_conv to produce a latent tensor z with shape [1, 256, 24, 24], representing 576 spatial patches with 256 features each. section 11.5.2
- Quantize every feature vector by selecting the nearest vector from VQGAN’s 1,024-entry codebook. section 11.5.2
- Flatten the 24 × 24 assignments into 576 integers, where each integer identifies a codebook vector. section 11.5.2
Encoding and reconstructing an image
Load a pretrained VQGAN, process a fish or cat image, run model.encoder(image), and pass the result through model.quant_conv. Then call model.quantize(z) to obtain codebook indices. Looking up those indices recreates the quantized latent representation; passing it through post_quant_conv and the VQGAN decoder reconstructs an image closely resembling the input. section 11.1 section 11.5.2
The discrete sequence serves as an interface between image compression and generation. In DALL-E mini, a transformer learns to predict VQGAN image tokens from caption representations; the VQGAN decoder then turns predicted tokens back into an image. section 1.2.2 section 12.1.1
Figure 11.2 A pretrained VQGAN model reconstructs an image. The left image shows the original fish image. The VQGAN encoder transforms this image into a sequence of 576 integers, representing its compressed latent code. The VQGAN decoder then reconstructs the image from this sequence, producing the version shown on the right. The reconstructed image closely resembles the original, demonstrating the effectiveness of the VQGAN in capturing and preserving key visual features through discrete latent representations.
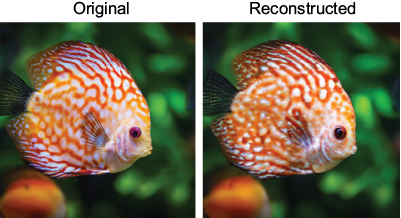
Compare the original fish image with its reconstruction and observe how discrete latent tokens preserve key visual features. section 11.1
