A backend predictor is the model-specific execution component behind a prediction API. It receives forwarded inference requests, loads model files, executes prediction logic, and returns results. section 7.1.2 section 7.5.2
In a model service, the frontend owns the public API and model-file retrieval, while the predictor reads models from a shared disk volume. A self-built predictor can support several models of one model family. section 7.1 section 7.1.2
A typical request workflow is:
- Accept a request containing a model identifier and input text. section 7.1.2
- Load the selected model from shared storage into memory. section 7.1.2
- Preprocess inputs, execute the model, postprocess outputs, and return the prediction. section 7.5.2
Runtime model selection
A prediction request can specify a model name and version or a model ID. The routing layer consults model metadata, downloads the files, selects the appropriate predictor by algorithm type, and forwards the request. section 7.5.2
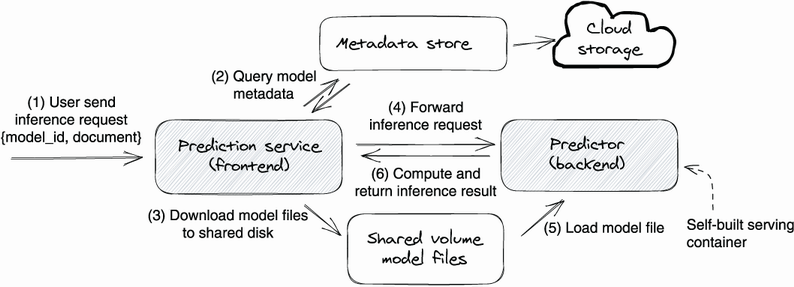
Trace the frontend, metadata store, shared volume, and backend predictor through an end-to-end serving request. section 7.1.2
