A routing component selects the inference backend for each prediction request. Because serving backends usually support only particular model types, routing enables one prediction platform to serve models across different frameworks through a unified API. section 6.3.3 section 6.4
For each prediction request, the component:
- Fetches the model metadata, including the algorithm name, model version, training framework, and metadata version information. section 6.3.3
- Matches that metadata against routing configuration to identify a compatible inference backend. section 6.3.3
- Forwards the prediction request to the selected inference server. section 6.3.3
Selecting framework-specific servers
A platform can route TensorFlow models to TensorFlow Serving and PyTorch models to TorchServe. The client uses the common prediction interface while the routing component chooses the framework-specific backend. section 6.3.3
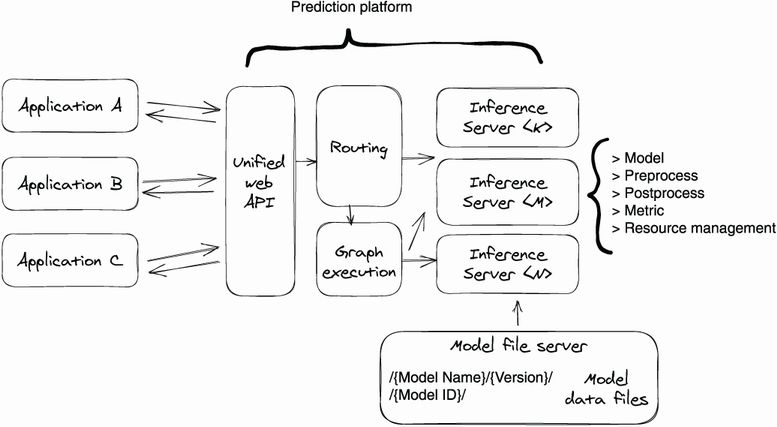
Use the general prediction-service architecture to locate the routing component between the unified prediction API and multiple model-server backends. section 6.3.3
