A self-defined dataset format separates dataset management from model-training frameworks. It provides an intermediate representation so training code does not have to depend on PyTorch or TensorFlow dataset formats. section 2.2.6
A dataset can use two strongly typed schemas:
- Ingestion schema: accepts a CSV whose first column contains text utterances and remaining columns contain labels. section 2.2.6
- Training schema: produces a ZIP containing examples.csv for utterance-to-label-ID mappings and labels.csv for label-name mappings. section 2.2.6
- A data-management service transforms ingestion data into training data, allowing collection and training development to proceed independently. section 2.2.6
TEXT_INTENT representation
An utterance such as “I couldn’t purchase gas in Costco” can map to label ID 2 in examples.csv, while labels.csv maps 2 to card_not_working. section 2.2.6
Figure 2.15 Each type of dataset has two data schemas: ingestion data schema and training data schema. These two schemas will ensure that the data we accept and the data we produce follow our data spec.
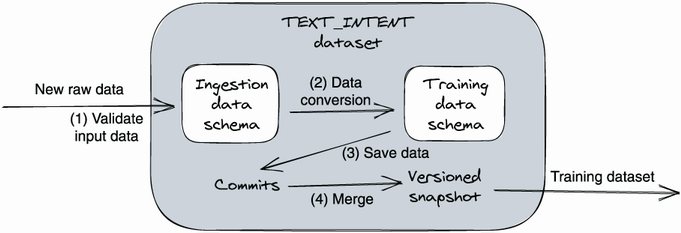
Shows how ingestion and training schemas define the accepted and produced data specifications. section 2.2.6
