Watkins's Q(λ) combines off-policy Q-learning with eligibility traces, which carry credit backward to recently visited state–action pairs. Because Q-learning can learn a greedy policy while an agent explores, a non-greedy action breaks the greedy trajectory: reset all traces to zero rather than assigning later rewards to earlier steps. section 6.5 section 6.7
This conservative reset preserves Q-learning's off-policy character, but frequent exploration can slow learning. Peng's Q(λ) and importance-sampling alternatives handle traces differently; for many tabular applications, SARSA(λ) avoids this trace-cutting issue. section 6.5
Figure 6.10 Integrating eligibility traces with Q-learning using Watkins's Q(λ) method.
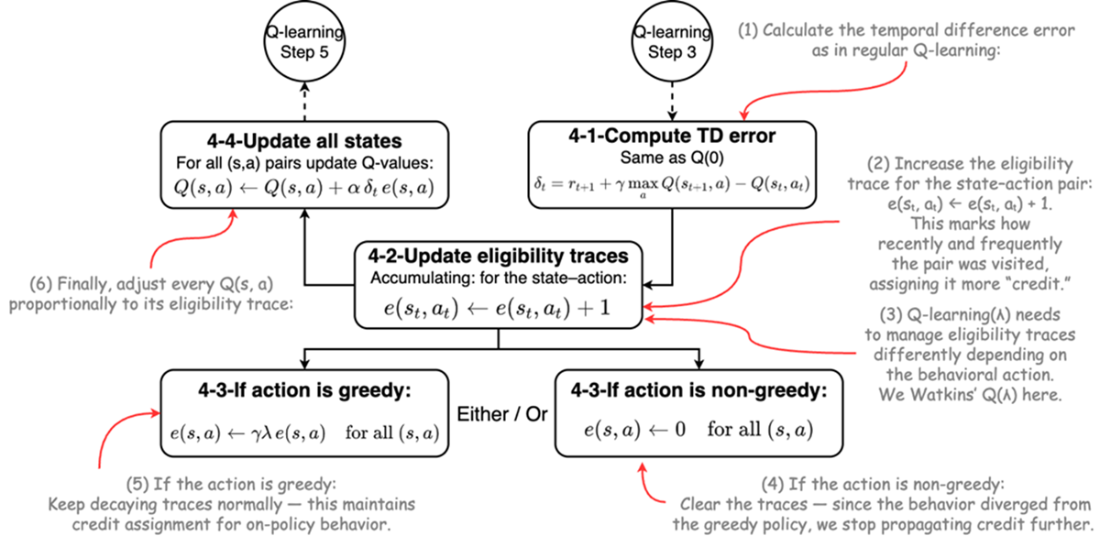
See the Q-learning update with eligibility traces and Watkins's reset rule. section 6.5
