WGMMA (Warp-Group-level Matrix Multiply-Accumulate) is a Tensor Core instruction that performs fast, low-precision matrix-multiply bursts for operations such as y = Wx. section 5.6.3
Its role in precision-managed accumulation is defined by three architectural steps:
- Consumes FP8 activation and weight tensors as GEMM inputs. section 5.6.3
- Accumulates intermediate products in a limited-precision Tensor Core register. section 5.6.3
- At a fixed interval Nc, promotes partial sums to CUDA Cores for final accumulation in an FP32 register, reducing underflow risk. section 5.6.3
Y_ij = W_i1*X_1j + W_i2*X_2j + ... + W_ik*X_kj
Use the matrix equation to follow how WGMMA contributes products to each output element. section 5.6.3
Figure 5.31 The Increasing Accumulation Precision mechanism in detail. Low-precision accumulation happens in bursts on the Tensor Core, and results are periodically promoted to a high-precision FP32 register on the CUDA Core.
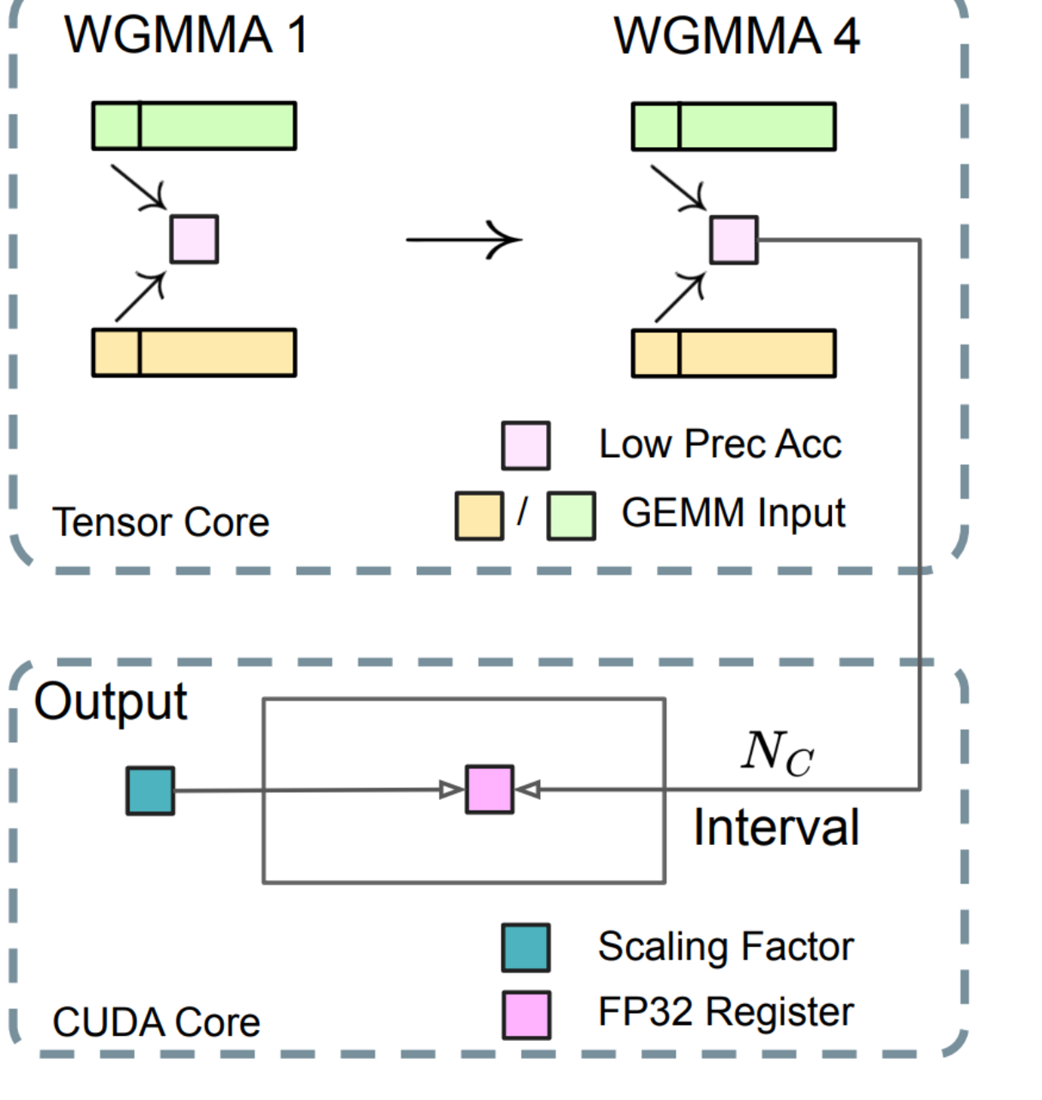
Trace the alternating fast low-precision Tensor Core bursts and periodic high-precision CUDA Core accumulation. section 5.6.3

