Whisper turns speech in an audio recording into text. OpenAI trained it on 680,000 hours of multilingual audio, helping it handle varied accents, languages, and recording conditions. It can run offline, so audio need not leave your machine. section 9.1
Whisper first converts audio into a spectrogram, a representation of sound frequencies over time. An encoder processes that representation; a decoder uses its output and tokens specifying the language and task to generate a transcript. section 9.1
Figure 9.1 Whisper’s encoder-decoder architecture. Audio is converted into a spectrogram, which the encoder processes. The decoder processes the encoder’s output together with control tokens to generate a transcript.
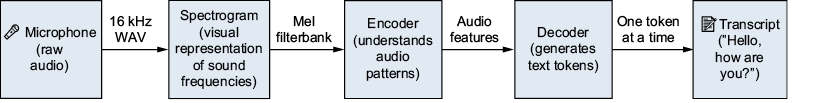
Follow the path from audio through the spectrogram and encoder to the decoder’s transcript. section 9.1
For a local Python voice-input application:
- Prepare mono, 16 kHz audio. Processing uses float32; WAV files can use int16. section 9.11
- Record with sounddevice.rec() and wait for completion with sd.wait(). section 9.11
- Transcribe with mlx_whisper.transcribe(path, path_or_hf_repo=model), then read result["text"]. MLX Whisper is optimized for Apple silicon. section 9.11
Whisper models range from tiny to large-v3. Start with small if memory is limited; try medium with more unified memory, and choose large-v3 only when its accuracy benefit warrants the extra memory and latency. Reusable record_and_transcribe() and transcribe_file() functions can provide voice input for a chatbot. section 9.11 section 9.0

