liveBook · Manning

XLM-RoBERTa

As explained in LLM Evaluation and Alignment, The Foundational Ideas

XLM-RoBERTa is a multilingual transformer language model that represents text from many languages in a shared embedding space.

XLM-RoBERTa is a multilingual BERT variant that encodes text from different languages into a shared semantic vector space. section 3.3.3

Within COMET, XLM-RoBERTa supports cross-lingual comparison by:

  • Independently encoding the source, candidate, and reference into embedding vectors. section 3.3.3
  • Placing German, English, and other language texts in the same space so their meanings can be compared. section 3.3.3
  • Providing embeddings that COMET combines into interaction features for predicting translation quality. section 3.3.3

Translation-quality example

For the German source “Die Bank war voller Kunden,” XLM-RoBERTa encodes the source, the English candidate “The bank was full of customers,” and the reference “The financial institution was crowded with clients” into comparable representations. section 3.3.3
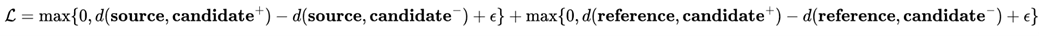
The architecture figure shows independent cross-lingual encoding, pooling into sentence embeddings, and downstream COMET scoring or ranking. section 3.3.3

How LLM Evaluation and Alignment, The Foundational Ideas covers it

How deep it goes
Explains independent encoding and shared embeddings, then stops short of detailing the encoder’s internal layers.
Examples
Uses a German source with English candidate and reference translations to demonstrate shared-space encoding.
What you can do after
Apply it via COMET to represent multilingual source, candidate, and reference texts for quality scoring.
How it connects
Connects multilingual embeddings with BERT and COMET’s feature extraction and quality prediction.

Related concepts

This explainer was generated by Manning's knowledge graph from the text of LLM Evaluation and Alignment, The Foundational Ideas. The section links point to the parts of the book it draws on.