Top-k Sampling
Top-k sampling is a technique used in the field of natural language processing to enhance the quality of text generation. It works by restricting the selection of tokens to the top-k most likely candidates, effectively masking all other tokens with a negative infinity value. This approach is particularly useful when combined with temperature scaling, as it helps focus on a subset of probable tokens, thereby reducing the likelihood of generating nonsensical outputs.
How Top-k Sampling Works
In top-k sampling, the process begins by identifying the top-k tokens with the highest logits, which are essentially the raw, unnormalized prediction scores from a model. All other tokens are then excluded from the selection process by setting their probability scores to negative infinity. This masking ensures that when the softmax function is applied, the probability distribution assigns a value of 0 to all non-top-k tokens. Consequently, the probabilities of the top-k tokens are normalized to sum up to 1.
The following figure illustrates the top-k sampling process with k set to 3:
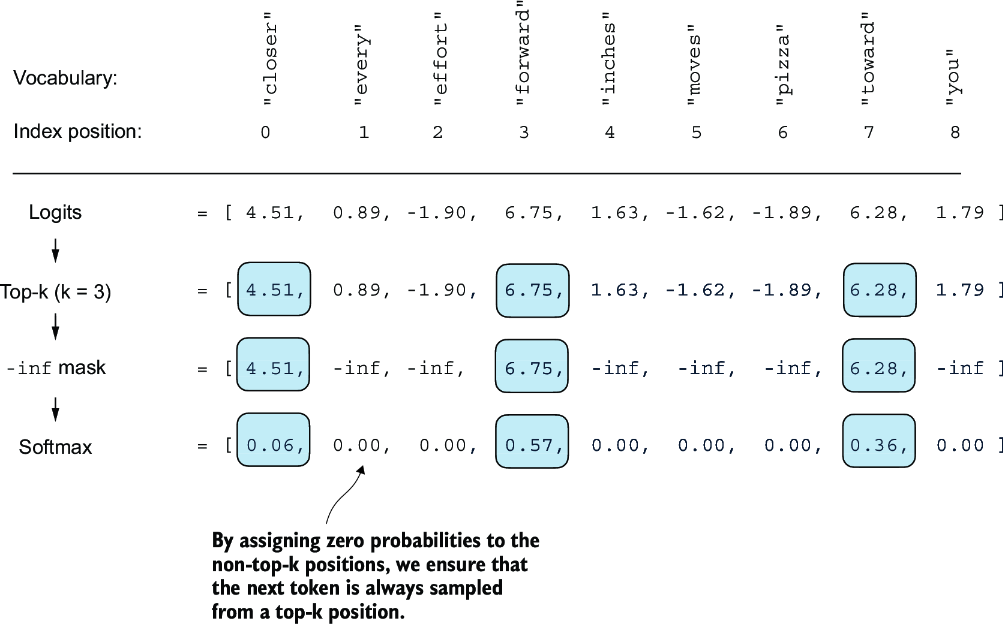 Figure 5.15 Using top-k sampling with k = 3, we focus on the three tokens associated with the highest logits and mask out all other tokens with negative infinity (–inf) before applying the softmax function. This results in a probability distribution with a probability value 0 assigned to all non-top-k tokens. (The numbers in this figure are truncated to two digits after the decimal point to reduce visual clutter. The values in the “Softmax” row should add up to 1.0.)
Benefits of Top-k Sampling
The primary advantage of top-k sampling is its ability to improve text generation results by narrowing down the selection to the most probable tokens. This method reduces the risk of selecting unlikely tokens that could lead to incoherent or irrelevant text. By focusing on a smaller, more likely set of tokens, top-k sampling helps maintain the coherence and relevance of the generated text.
In summary, top-k sampling is a powerful technique that, when used in conjunction with probabilistic sampling and temperature scaling, can significantly enhance the quality of text generated by language models.