An accumulator is a hardware register that stores the running sum of products in a matrix-multiplication dot product. For Y = WX, each product WᵢₗXₗⱼ is added into the accumulator until one output element is complete. With FP8 inputs, limited accumulator precision becomes a hardware bottleneck: large inner dimensions such as k = 4096 require thousands of additions, and insufficient precision can cause underflow and substantial numerical error. section 5.6.3
The expanded dot-product equation makes each accumulation step explicit. section 5.6.3
Increasing accumulation precision separates fast low-precision multiplication from more precise summation. Tensor Cores accumulate products in bursts, then periodically promote intermediate results to an FP32 register on CUDA Cores. This uses specialized units for throughput while reducing error from prolonged low-precision accumulation. section 5.6.3
Figure 5.30 The core strategy for increasing accumulation precision: intermediate results are periodically moved from the low-precision environment of the Tensor Cores to the high-precision environment of the CUDA Cores.
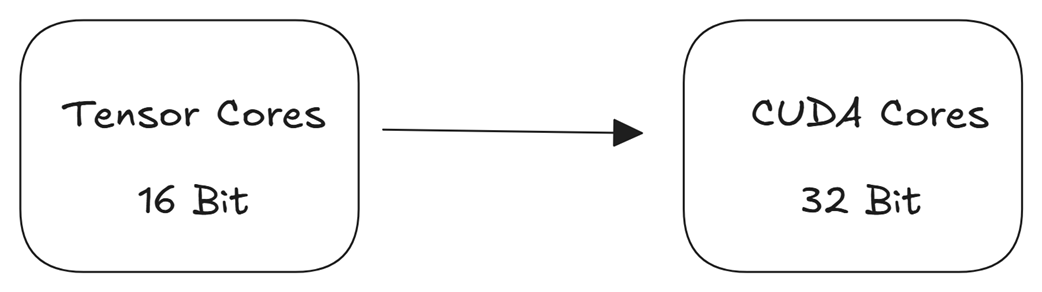
The figure traces intermediate results moving from the low-precision Tensor Core environment to higher-precision CUDA Core storage. section 5.6.3