An adversarial input is a sample changed in a small, often deliberate way to make a machine-learning model produce the wrong output. It exposes a gap between model sensitivity and human perception. section 19.1.2
A panda classified as a gibbon
Gradient ascent can slightly modify a panda image to maximize the model’s prediction for “gibbon.” The altered image may look unchanged to people while overturning the model’s classification. section 19.1.2
Related sensitivity appears in several forms:
- Image models can be tricked by carefully designed pixel changes. section 19.1.2
- LLMs can fail when names, places, numbers, or code variable names change slightly. section 19.1.2
Figure 19.3 An adversarial example: imperceptible changes in an image can upend a model’s classification of the image.
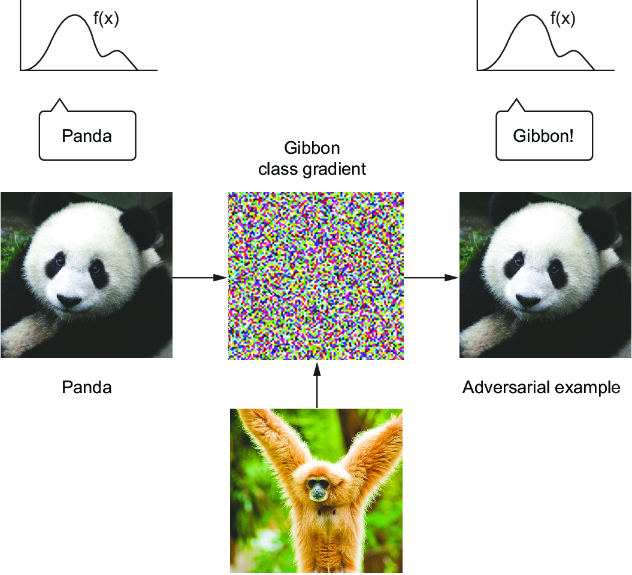
Use the figure to inspect how imperceptible image changes can reverse a model’s classification. section 19.1.2




