Apache Arrow is a standardized, in-memory columnar format for exchanging analytical data efficiently across systems and programming languages. It reduces serialization overhead and enables zero-copy reads. section 8.2.3
In a federation layer, Arrow supports high-performance connectivity alongside JDBC, ODBC, and REST. Arrow Flight transports Arrow-formatted data between processes through a gRPC-based protocol. section 8.2.3
Arrow’s implementation role includes:
- Providing a common columnar representation for analytical processing across heterogeneous systems. section 8.2.3
- Supporting vectorized execution and lower memory overhead in Dremio’s query engine. section 8.3.4
- Enabling zero-copy data exchange with BI tools and data science notebooks connected through Arrow Flight. section 8.3.4
- Extending modern database access through ADBC and Arrow Flight SQL as alternatives to JDBC and ODBC. section 8.2.3
Arrow in Dremio
Dremio combines Apache Arrow with distributed execution, caching, and reflections to reduce latency when querying cloud storage, databases, raw files, and Iceberg tables. Reflections can transparently accelerate repeated scans and analytical queries. section 8.3.2 section 8.3.4
Figure 8.4 By using industry-standard interfaces like JDBC, ODBC, Arrow Flight, and platform-specific REST APIs, customer software, AI, and BI can communicate with all the data accessible in your federation layer. In this figure, each interface delivers data to AI, BI, and custom data applications.
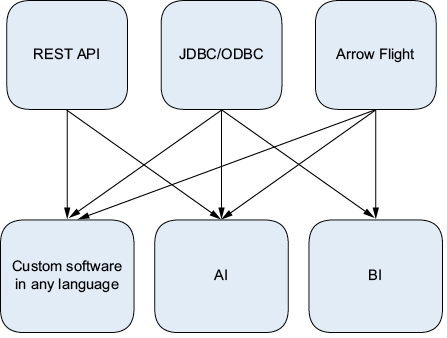
Trace how Arrow Flight fits among JDBC, ODBC, REST, and other interfaces connecting federated data with BI, AI, and custom applications. section 8.2.3


