An attention head is an independently parameterized perspective within self-attention. It learns which tokens relate to one another using its own query, key, and value matrices. section 11.22
Self-attention lets every token decide how much other tokens should influence its meaning. One head might focus on adjectives, while another focuses on nouns or pronouns. section 11.17 section 11.22
Tracing relationships in a sentence
In “Alice was beginning to get very tired,” the token “tired” can look back to “Alice” to identify who is tired and to “very” to determine how tired. Different heads can learn different relationships in parallel. section 11.17 section 11.22
Multiple heads expand the model’s representational coverage:
- Each head learns a distinct type of connection, such as grammar, pronouns, or token position. section 11.22
- The model combines all heads’ findings into a richer representation of each token. section 11.22
- For width 8, the design can use one 32×8 head, two 32×4 heads, or four 32×2 heads. section 11.22
Figure 11.40 An analogy of the usefulness of multiple attention heads
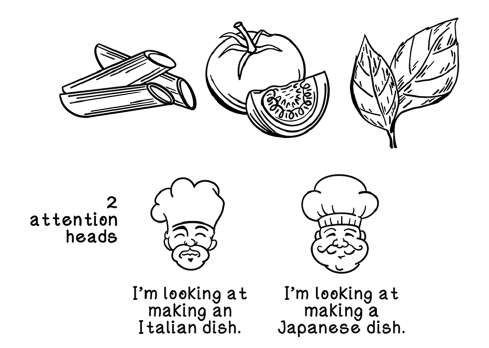
Use the chef analogy to visualize heads as specialists examining the same ingredients from different perspectives. section 11.22

