An attention head is one independent self-attention mechanism inside a transformer layer. Multiple heads attend to different aspects of the same sequence, allowing distinct word relationships or meanings to be represented in separate vector subspaces. section 9.1.2
Each head projects input embeddings into query, key, and value matrices. Query–key multiplication produces a square connection or scoring matrix; normalized scores weight the values. The heads’ outputs are concatenated and projected through an output matrix. section 9.1.2
A multi-head attention computation proceeds by:
- Creating separate query, key, and value projections with head-specific dimensions. section 9.1.2
- Computing attention scores that connect positions across the input sequence. section 9.1.2
- Concatenating the value outputs from all heads and applying the shared output projection. section 9.1.2
Transformer and BERT configurations
The original Transformer uses eight attention heads, with key and value dimensions of 64 when the model dimension is divided evenly. BERT base uses 12 layers, hidden size 768, and 12 heads; BERT large uses 24 layers, hidden size 1,024, and 16 heads. section 9.1.2 section 9.3.3
Equation 9.2 Multi-head self-attention
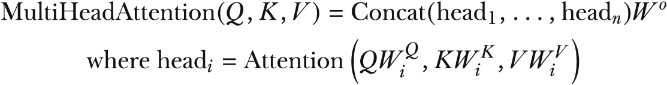
Use the multi-head self-attention equation to inspect how head-specific computations combine into one transformer output. section 9.1.2

