A student model is a smaller deployable model trained to reproduce behavior supplied by a larger teacher. In Self-RAG, distillation teaches the student to emit reflection tokens rather than relying on manually scripted inference rules. section 9.3.1
Behavioral distillation fine-tunes the student with ordinary cross-entropy loss on teacher-generated text. Unlike classical distillation, it exposes labeled examples rather than the teacher’s internal probability distributions. section 9.3.1
A Self-RAG student model carries control signals into inference:
- A critic annotates query-answer data with reflection tokens such as retrieval, relevance, support, and usefulness signals. section 9.3
- The student learns to generate those tokens alongside ordinary continuations. section 9.3
- Token-guided beam search reweights candidate sequences, allowing groundedness and creativity to be adjusted at runtime. section 9.3
- A threshold on the Retrieve-token probability decides whether to query a vector store or answer from parametric memory. section 9.3
Choosing a teacher
GPT-4 serves as a critic when API cost and data sensitivity permit. Open-weight critics suit private or on-premises data, while domain-specific critics can better judge specialized corpora. section 9.3.1
Figure 9.2 The full Self-RAG lifecycle: training, decoding, and adaptive retrieval. Left: the training phase (9.3.1) routes a raw query-answer dataset through a Critic model that annotates each example with inline reflection tokens, and the resulting traces fine-tune the Student model. Middle: the inference phase (9.3.2) shows the trained Student emitting candidate continuations alongside reflection tokens, with a token-guided beam search scoring each candidate by log P(text) + Σ w_T log P(T) over the IsRel, IsSup, and IsUse tokens, with w_T exposed as runtime knobs. Right: the adaptive retrieval gate (9.3.3) compares the Retrieve-token probability to a threshold; queries above it trigger the vector store, queries below it are answered from parametric memory.
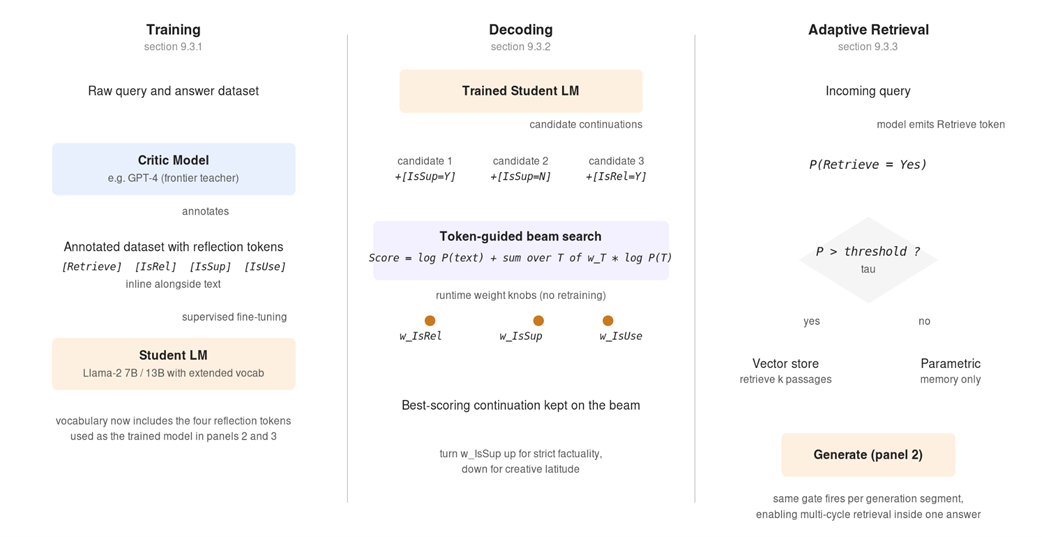
Trace the complete lifecycle from critic-annotated training data through student generation, token-guided decoding, and adaptive retrieval. section 9.3
