How does a language model turn familiar text into something it can process? Byte Pair Encoding (BPE) builds a vocabulary by repeatedly merging the most frequent adjacent symbols or tokens. section 2.1.1
The process works in a few simple steps:
- Start with individual characters such as “u,” “n,” and “b.” section 2.1.1
- Find the adjacent pair that appears most often and merge it into a new token. section 2.1.1
- Repeat the merge thousands of times until the vocabulary reaches its target size, typically 50,000–100,000 tokens. section 2.1.1
- Assign each final token an arbitrary numeric index for later processing. section 2.1.1
Common words and rare words
Frequent words such as “the” or “is” may become single tokens. A rarer word such as “unbelievable” may split into “un,” “believ,” and “able.” A small change in phrasing, even adding or removing a space, can therefore change the token sequence. section 2.1.1
Figure 2.1 The same word, seen in two ways. A human reads "unbelievable" as a single unit of meaning. A model never sees the word at all: it receives three tokens and three numbers.
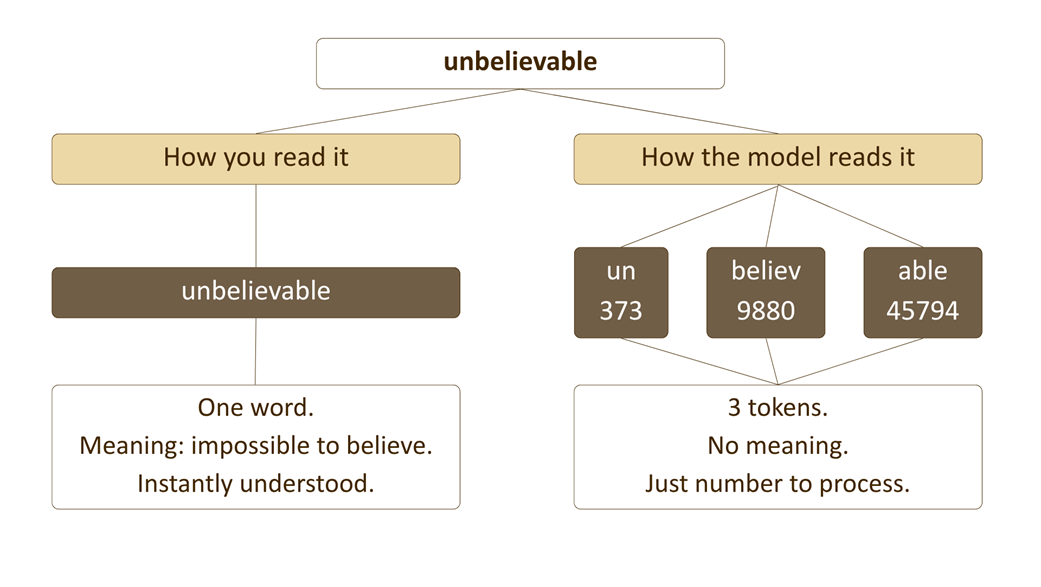
Compare the human view of “unbelievable” as one meaningful word with the model’s input: three tokens followed by three numbers. section 2.1.1













