A cloud storage provider is a service that stores files remotely and exposes them for network access. In Snowflake pipelines, it supplies files for ingestion through an external stage. section 3.0 section 1.1.2
A typical pipeline authenticates to the provider, exposes its files through an external stage, loads them into a staging table, and inserts or merges them into a target table. Provider-specific stage syntax depends on whether the files reside in Amazon S3, Google Cloud Storage, or Microsoft Azure Blob Storage. section 3.0
Common ingestion choices include:
- Use the COPY command with an external stage for loading files into Snowflake tables. section 3.0
- Create external tables to query files where they reside in cloud storage. section 3.0
- Use Snowpipe for continuous ingestion when provider notifications identify newly available files. section 1.1.2
- Prepare files for efficient ingestion and consider materialized views when query performance requires improvement. section 3.0
Azure-hosted CSV pipeline
A pipeline can read CSV files from Microsoft Azure Blob Storage through an external stage, load them into a staging table, and merge them into a target table. The same pattern can be adapted to Amazon S3 or Google Cloud Storage with provider-specific syntax. section 3.0
Figure 3.1 A data pipeline that takes CSV files from a cloud storage location makes the files available to Snowflake in an external stage, either by using a storage integration object or by providing credentials, loads the data into a staging table, and inserts or merges the data from the staging table into the target table.
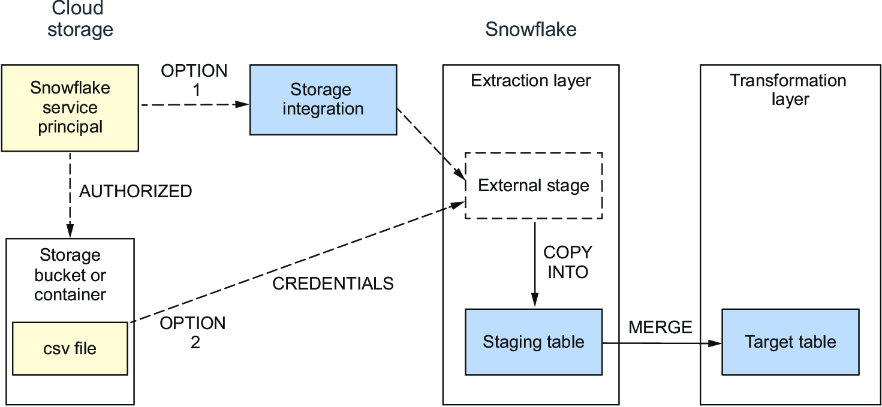
Trace the flow from cloud storage through authentication and an external stage to staging and final table loading. section 3.0
