Cross-attention is multihead attention in which queries come from one representation source while keys and values come from another. In an encoder-decoder transformer, the decoder supplies queries and the encoder supplies keys and values, linking generated output positions to the input sequence. section 11.3
The encoder-decoder arrangement works as follows:
- Treat the encoder representation as a database of keys and values. section 11.3
- Use the decoder’s target sequence as the query source. section 11.3
- Associate each target word with related input words while generating the output sentence. section 11.3
- Combine this operation with masked self-attention, which preserves causality during one-token-at-a-time generation. section 11.3
Neural machine translation
While translating, the decoder queries the encoded input sentence to determine which input words are relevant to the next output word. section 11.3
Figure 11.10 Transformer architecture
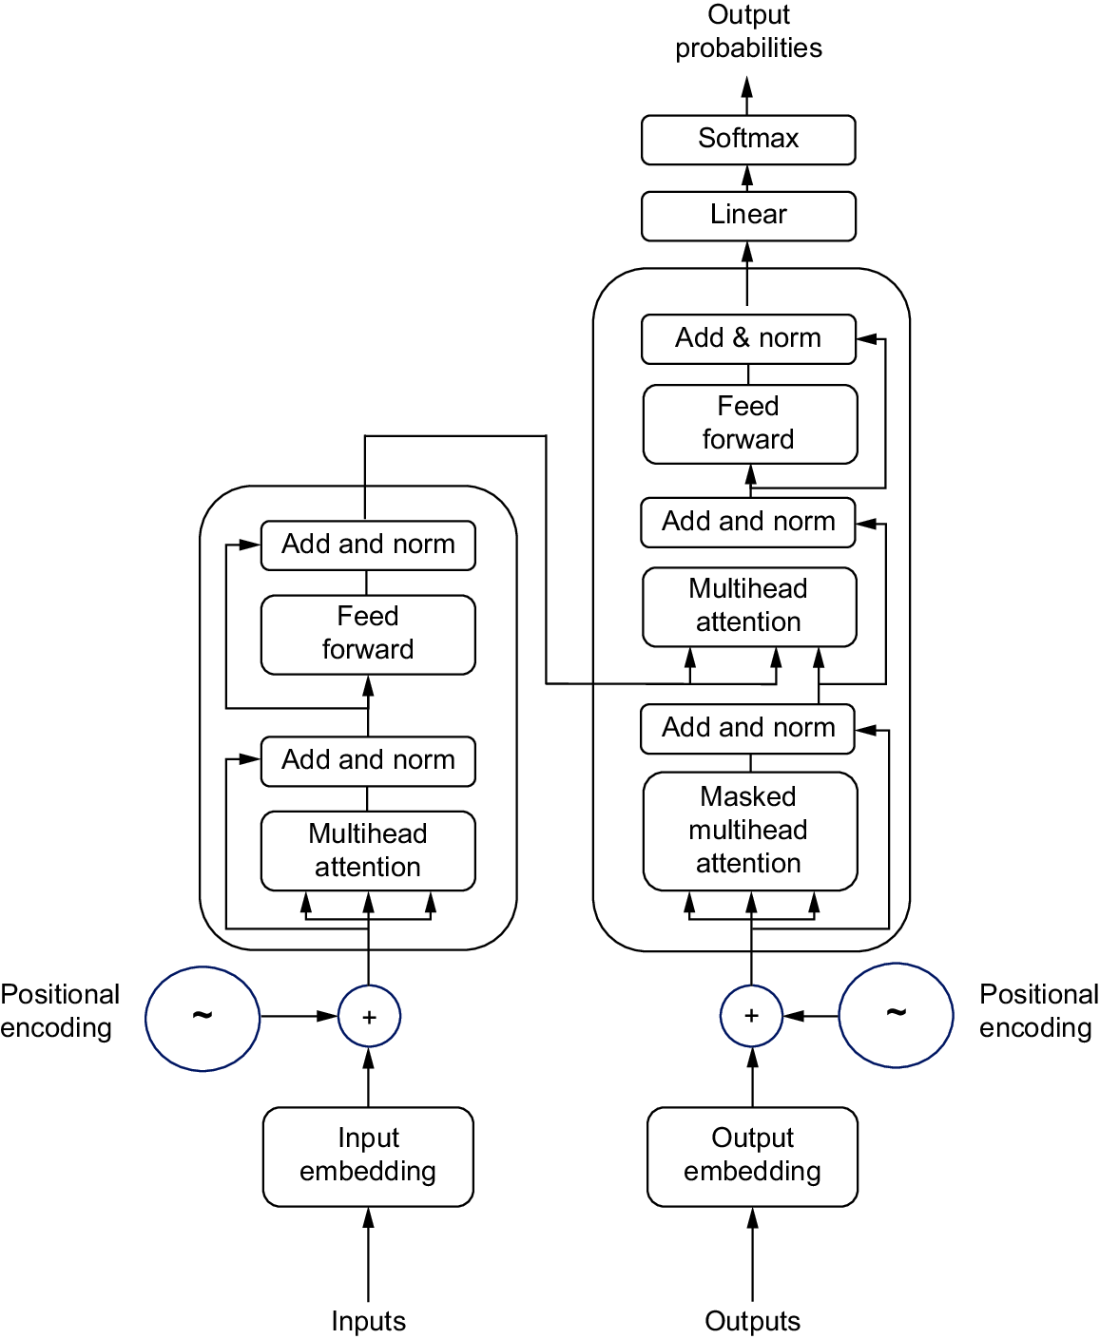
Use the transformer architecture figure to locate encoder-decoder attention alongside the decoder’s other attention components. section 11.3



