A CUDA program moves data between CPU (host) memory and GPU (device) memory. Its common five-step workflow is allocate device memory, copy input to the GPU, compute, copy results back, and free device memory. section 2.14
Figure 2.6 The CUDA data lifecycle, five steps from CPU to GPU and back: allocate GPU memory, copy data in, run the kernel, copy results out, and free the memory.
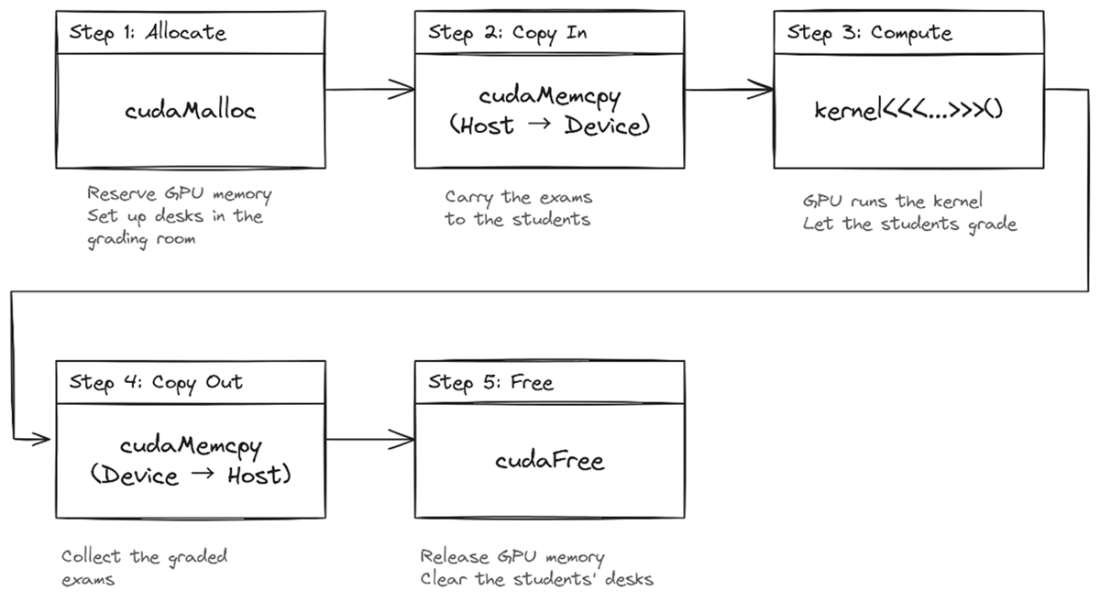
Follow the data’s trip from CPU to GPU and back through the five steps. section 2.14
For an array, the steps use these CUDA operations:
- Allocate device memory with cudaMalloc. section 2.14
- Copy input from host to device with cudaMemcpy and cudaMemcpyHostToDevice. section 2.14
- Launch a kernel to compute, then call cudaDeviceSynchronize() before relying on its results. section 2.19
- Copy results back with cudaMemcpy and cudaMemcpyDeviceToHost. section 2.19
- Release device memory with cudaFree when it is no longer needed. section 2.19
Squaring an array
For a small array of numbers, allocate a device array, copy the input over, launch a kernel that squares each element, wait for the kernel, copy the squares back, and free the device array. A missing copy-in can leave the kernel operating on uninitialized GPU memory, producing zeros or garbage instead of correct results. section 2.14 section 2.19
