A scheduled data pipeline needs to know which time slice each DAG run should process. Airflow provides data_interval_start as the beginning of that run’s data interval, paired with data_interval_end. section 3.4.4
Interval-based schedules execute after an interval has passed, while exposing its boundaries to tasks. This makes the interval explicit for incremental processing; logical_date generally identifies the interval by its start. section 3.4.4 section 3.8
Use data_interval_start to:
- Select the beginning timestamp for the current processing window. section 3.4.4
- Build date- and time-dependent paths or URLs for downloaded data. section 5.2
- Receive the value explicitly in a PythonOperator callable or retrieve it from the task context. section 5.2.2
Use the interval start in a Python task
def _get_data(data_interval_start, **context): year, month, day, hour, *_ = data_interval_start.timetuple() url = ( "https://dumps.wikimedia.org/other/pageviews/" f"{year}/{year}-{month:0>2}/" f"pageviews-{year}{month:0>2}{day:0>2}-{hour:0>2}0000.gz" ) PythonOperator(task_id="get_data", python_callable=_get_data) A callable can instead accept **context and read context["data_interval_start"]. Pair the start with data_interval_end when the task needs the complete interval. section 5.2 section 5.2.2
Figure 3.8 Time represented in terms of Airflow’s scheduling intervals, assuming a daily interval with a start date of 2024-01-01. Execution happens at the end of the interval (e.g., the DAG run for the first interval is executed at 2024-01-02 00:00).
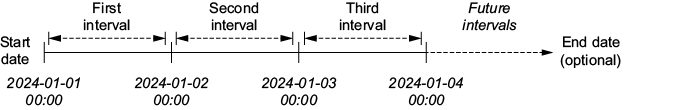
View how daily intervals are positioned in time and why execution occurs after the interval ends. section 3.4.4
