A data lake is a centralized landing place for large volumes of raw structured and unstructured data. It preserves source formats without requiring a predefined schema, then supports later cleaning, transformation, and analysis. section 11.2.2 section 11.5
A practical data-lake workflow includes:
- Collect wide data from many tables and sources, as well as big data with high record volumes. section 11.2.2
- Retain data in its source format before curating it into clean, structured, accurate tables in a data warehouse. section 11.2.2
- Apply cleaning, transformation, and data-quality checks for inaccuracies, null records, and schema changes. section 11.2.2 section 11.5
Infrastructure recommendation
Evaluate whether a data lake fits a company collecting app views and clicks, customer sign-ups across free and paid tiers, and renewable-energy purchases and installations. Compare storage options, weigh their pros and cons, and justify a recommendation based on anticipated analytical needs over the next one to two years. section 11.2.4
Figure 11.8 Data lakes are the first landing point for the data that organizations synthesize for analysis.
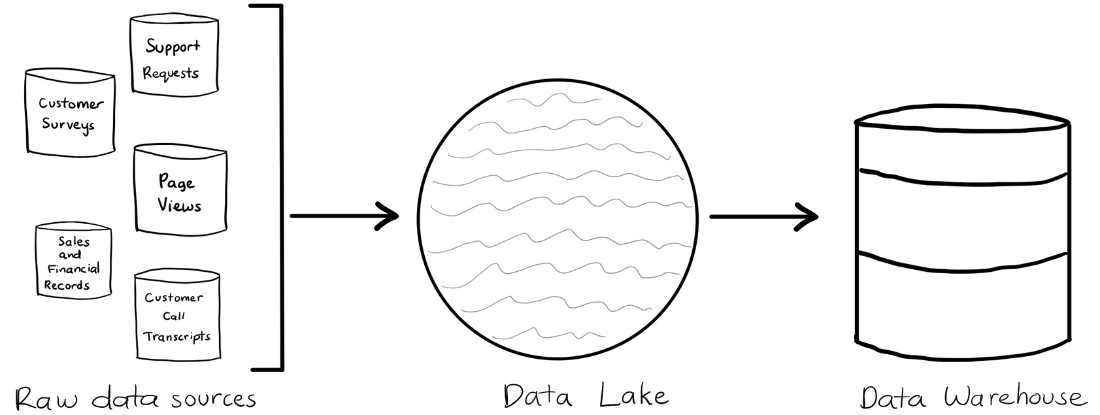
Use the diagram to visualize a data lake as the first landing point for information synthesized for analysis. section 11.2.2


