A Kubernetes service running LLM inference can need more replicas even when CPU and memory metrics do not capture the pressure on its GPUs. NVIDIA Data Center GPU Manager (DCGM) supplies GPU metrics through an exporter, making GPU utilization available as a signal for autoscaling. section 6.2.2
The metrics serve different purposes:
- GPU utilization and GPU memory utilization are the most useful DCGM metrics for autoscaling. section 6.2.2
- Temperature and power usage can also support monitoring dashboards. section 6.2.2
DCGM does not, by itself, make Kubernetes scale a deployment. Its exporter supplies metrics to a monitoring system such as Prometheus, which collects and stores them. Kubernetes’ default metrics endpoint exposes CPU and memory metrics, not GPU metrics; a custom or external metrics API is also needed to make a GPU signal available to the horizontal pod autoscaler. KEDA is one tool used in that arrangement. section 6.2.2 section 6.5
Figure 6.7 Autoscaling based on a custom metric like GPU utilization requires several extra tools to work, including NVIDIA’s DCGM, a monitoring system like Prometheus Operator, and a custom metrics API like that provided by KEDA.
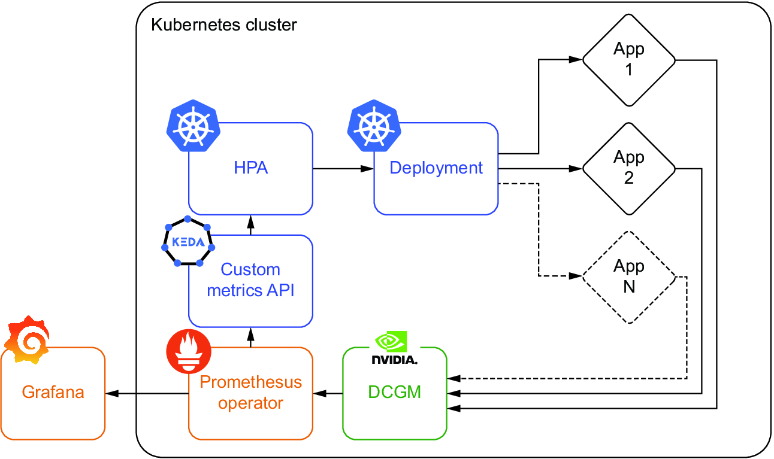
The diagram shows why GPU-based autoscaling needs more than an exporter: monitoring and a custom metrics API bridge the gap to Kubernetes autoscaling. section 6.2.2
