A GPU-backed LLM service can be busy even when CPU and memory usage do not tell the whole story. Kubernetes horizontal pod autoscalers can adjust application replicas using CPU and memory, but GPU-based autoscaling needs custom metrics. Scaling up helps protect reliability under load; scaling down frees resources and cuts costs. section 6.2.2 section 6.5
NVIDIA’s Data Center GPU Manager (DCGM) can export GPU metrics. For autoscaling, the most useful are GPU utilization and GPU memory utilization. Temperature and power usage are also available, though they are more useful for dashboards than for the scaling decision described here. section 6.2.2
Figure 6.7 Autoscaling based on a custom metric like GPU utilization requires several extra tools to work, including NVIDIA’s DCGM, a monitoring system like Prometheus Operator, and a custom metrics API like that provided by KEDA.
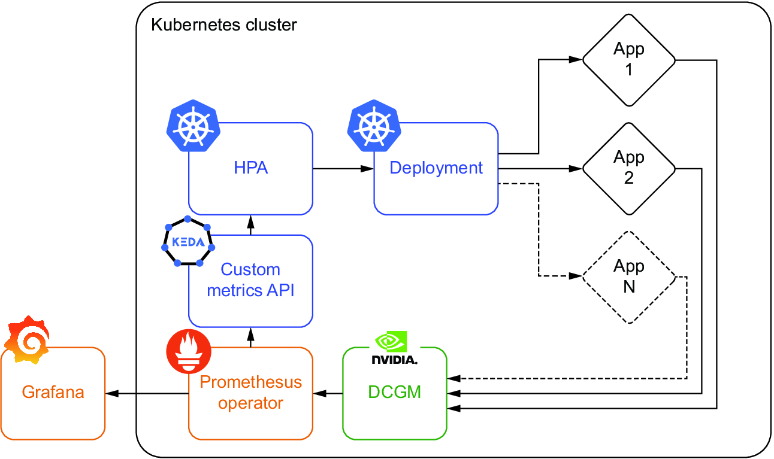
The diagram shows why GPU-based autoscaling needs more than the built-in CPU-and-memory HPA: DCGM supplies metrics, Prometheus collects them, and KEDA provides a custom metrics API. section 6.2.2
Prometheus collects exported measurements and stores them as queryable time-series data. This makes GPU activity available to the additional services needed for custom-metric autoscaling. The practical trade-off is extra monitoring infrastructure in exchange for replica counts that respond to GPU load rather than CPU and memory alone. section 6.2.2 section 6.5
