Deduplication identifies and removes redundant records representing the same underlying entity or event, preventing inflated aggregates and misleading analysis. section 6.6.2
Treat deduplication as an EDA backlog task alongside join validation and normalization. Verify the result against plausible aggregates and published business figures before using the data for projections. section 6.6.2
Implementation checkpoints:
- Compare aggregates produced with and without deduplication to expose distortion. section 6.6.2
- Combine deduplication with a properly designed normalization process. section 6.6.2
- Cross-check corrected totals against published revenue and document material deltas in the EDA report. section 6.6.2
Figure 6.7 Naïve normalization and deduplication sales data
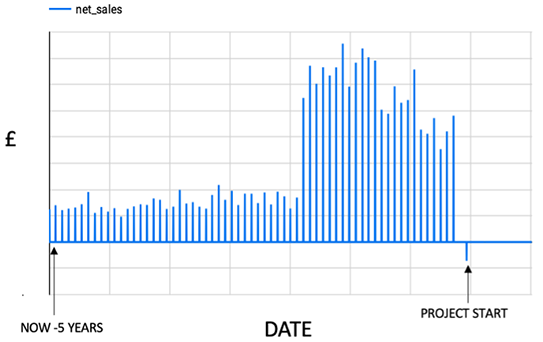
Compare naïve normalization and deduplication with the resulting aggregate sales picture. section 6.6.2
Figure 6.8 The same data treated for duplicates with a well-designed currency normalization process
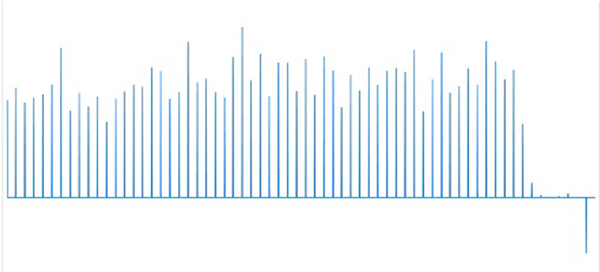
Inspect how duplicate treatment combined with currency normalization produces more plausible results. section 6.6.2




