DeepSeek-R1-Distill-Qwen-1.5B is a 1.5-billion-parameter Qwen2.5-Math-based language model fine-tuned on verified reasoning traces generated by DeepSeek-R1. It preserves the base model’s architecture and weights while transferring reasoning behavior through data rather than shrinking the 671B teacher’s parameters. Requiring about 3 GB of memory, it can run on a CPU or mobile device. section 8.1.2 section 8.9
Its practical profile follows from the base model, training recipe, and student capacity:
- Uses a math-specialized Qwen2.5-Math 1.5B base, giving distillation an existing mathematical vocabulary and pattern-recognition foundation. section 8.5.4
- Learns from an 800K curated dataset of teacher-generated traces: approximately 395K math, 211K code, 10K STEM, 10K logic, and 178K general samples. section 8.9
- Trains for 2–3 epochs with batch size 64, cosine learning-rate decay, a 32,768-token context limit, and an initial learning rate of 1 × 10⁻⁴. section 8.5.4
- Specializes in mathematical reasoning but lacks capacity for comparable coding performance; distillation transfers existing capability without extending the teacher’s frontier. section 8.7.1 section 8.9
Benchmark profile
On AIME 2024, the 1.5B model scores 28.9%, exceeding GPT-4o at 9.3% and Claude-3.5-Sonnet at 16.0%. It reaches 83.9% on MATH-500 but only 16.9% on LiveCodeBench, making the math-versus-coding trade-off explicit. section 8.7.1
Figure 8.3 The dramatic reduction in memory and GPU requirements from the 671B teacher model down to the smallest 1.5B distilled model, which runs on a phone.
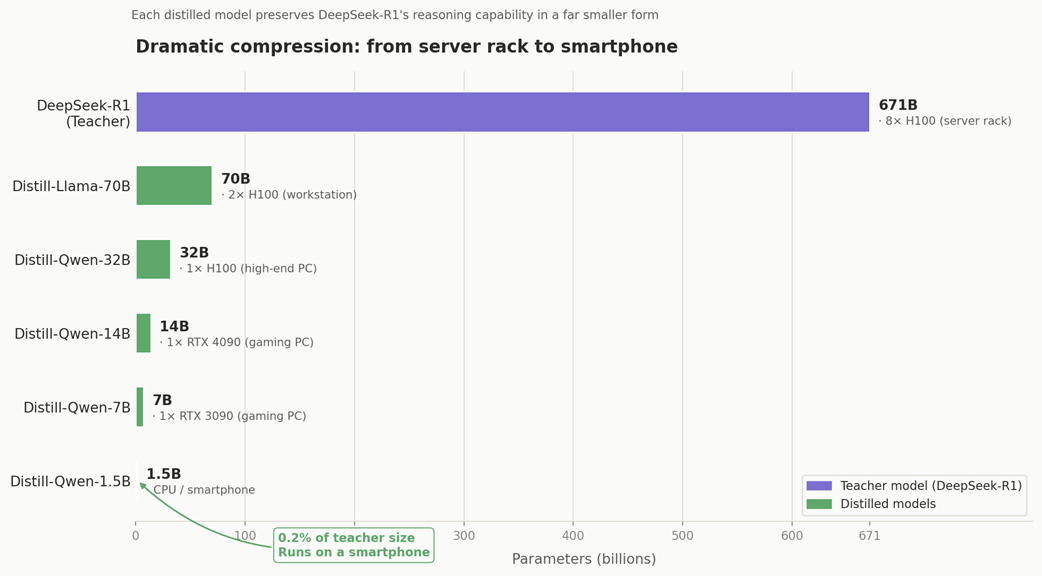
Use the memory-and-GPU comparison to visualize how a 671B teacher’s reasoning capability reaches a phone-deployable 1.5B student. section 8.1.2
