Dot-product attention turns relationships between sequence positions into weighted values. It projects embeddings into query, key, and value matrices, then compares queries with keys using scalar products. section 9.1.2
The computation proceeds in a compact matrix pipeline:
- Create Q, K, and V through linear projections of the input embeddings. section 9.1.2
- Multiply Q by K to score connections between words, scaling by 1/√dₖ for numerical stability. section 9.1.2
- Apply softmax so scores are positive and sum to 1, then multiply them by V to produce weighted values. section 9.1.2
Attention as word connections
The Q × K product forms a square attention matrix that can be read as connections between words in an input sequence. section 9.1.2
Equation 9.1 Self-attention outputs
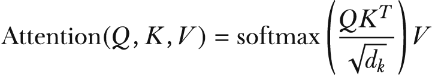
Use the self-attention equation to inspect how scaled scores become weighted outputs. section 9.1.2

