An embedded analytics database runs inside an application, notebook, or command-line process rather than through a separate network service. DuckDB applies this model to local analytical work, efficiently querying gigabytes across files, databases, and in-memory data structures. section 1.1 section 2.1
This deployment model connects directly to practical data workflows:
- Query CSV, JSON, Parquet, Apache Arrow, cloud-bucket or URL data without first loading everything into a separate server. section 1.1
- Use SQL from the CLI, or query pandas and Polars DataFrames from Python and notebooks. section 1.1 section 6.0
- Move query results into DataFrames or Apache Arrow tables for subsequent analysis. section 6.0
A practical starting point
Open the DuckDB CLI and query local analytical files directly; use the Python API when the surrounding workflow already operates on pandas or other Python objects. section 2.1 section 6.0
Figure 1.1 DuckDB and other tools in the ecosystem
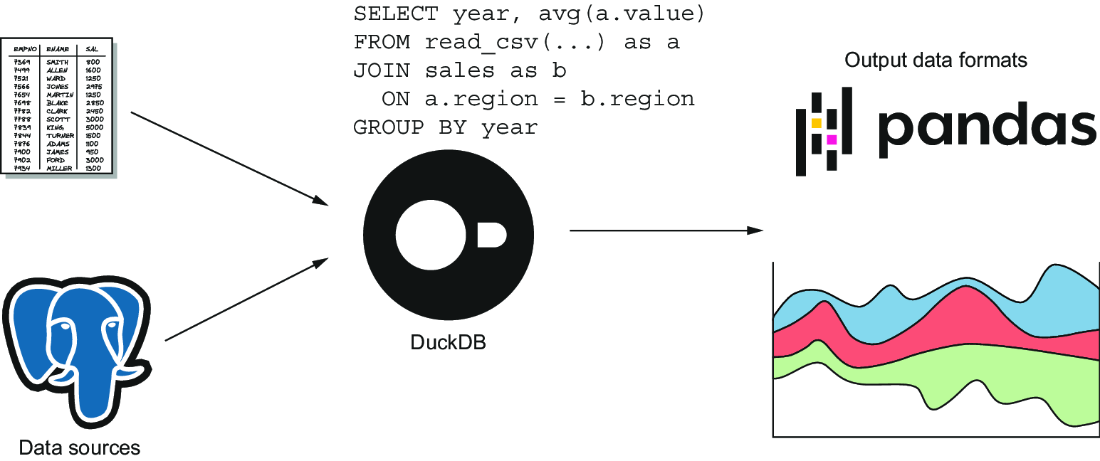
Use the ecosystem overview to place DuckDB alongside applications, file formats, Python tools, and other data systems. section 1.1
