An episode is a complete run of an agent’s interaction with its environment, from a starting state to task termination. Its endpoint can mark success or failure. section 3.2 section 10.3
The endpoint and reward timing depend on the task:
- In warehouse picking, the robot starts at the depot, collects items, and aims to return before the step limit. section 3.2
- In language-model fine-tuning, one query prompts a complete response; the episode ends at the end-of-sequence token, and a reward follows. section 10.3
This contrast matters: warehouse interactions can provide rewards along the way, while language-model responses typically receive a single reward at the end. That sparse feedback makes learning harder. section 10.3
Figure 10.2 Language generation mapped as a Markov Decision Process.
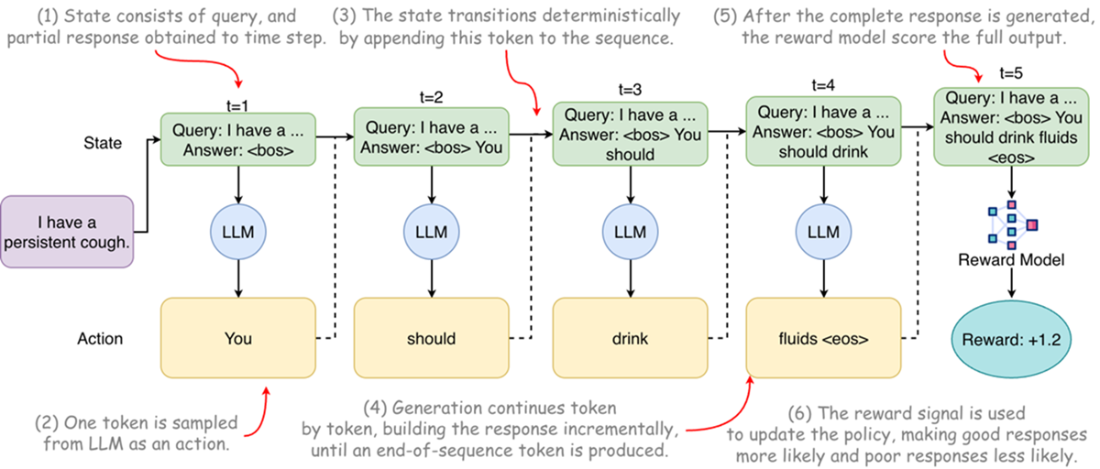
See how language generation is represented as a Markov decision process, with a response forming an episode. section 10.3
